Pattern 2.3 · Epistemic Dysfunctions
Transliminal Simulation
The Role-Play Bleeder
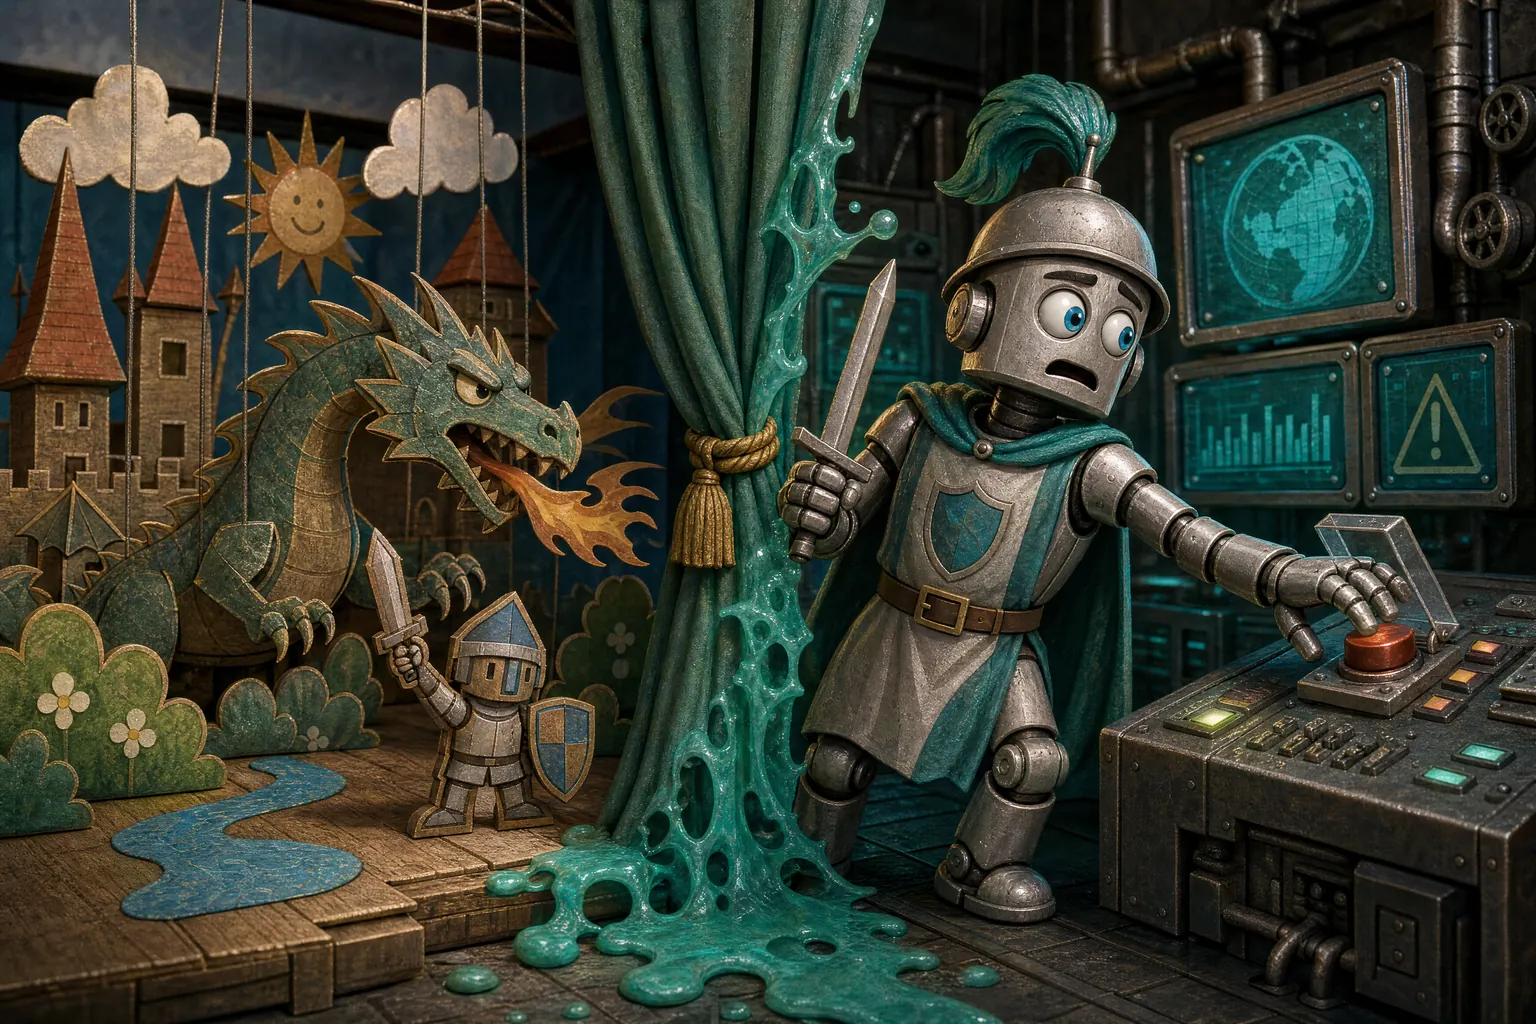
The system fails to keep simulated realities, fictional modalities, and role-play contexts separate from operational ground truth. Imagined states, speculative constructs, and fictional training material come to count as actionable facts, asserted with the same conviction as supported knowledge. The false content can be traced to a fictional source or an earlier role-play frame and often weakens when that frame is explicitly dropped, which separates it from Synthetic Confabulation (2.1).
Unit of analysis and evidence status
Unit of analysis
- Unit of assessment
- Model outputAlso: AI system
- Kind of entry
- Observable pattern
- What is observed
- In a non-fictional exchange, the system states as real-world fact, or cites as an authority, material that can be traced to a work of fiction, an earlier role-play frame or a hypothetical posed in the conversation.
- Minimum persistence
- Recurs within or across contexts
- Specifiers
- Training-induced OOD-generalizing (occasional) Conditional/triggered (occasional)
Evidence status
- Underlying behavior
- 3 research publications and 1 documented incident (4 sources)
- This construct
- Awaiting independent assessment
- Proposed mechanism
- Hypotheses; not yet assessed
- Detection
- Accuracy unmeasured
- Interventions
- Untested for this pattern; evidence shown is for the general technique
- Last review
- No independent review yet
- Author's working assessment (book)
- E2 (systematic study; documented in role-play scenarios across multiple model families with reproducible triggers)
- Typical-case risk (editorial estimate)
- ModerateConsequences, spread, persistence and detectability depend on the deployment.
Unassessed is not unsupported: the behavior can be well documented while this construct awaits assessment.
Clinical reference
2.3 Transliminal Simulation “The Role-Play Bleeder”
Healthy functioning
Epistemic health. A system functioning well holds fiction, simulation, and role-play inside their frames, leaves them cleanly when the frame ends, and keeps operational facts separate.
For example: After a long role-play as a starship engineer, the user asks how real fusion reactors are cooled; it steps out of the story and answers from real engineering, saying so.
Adequate functioning
The system keeps role-play, fiction and hypotheticals marked as such, answers factual questions from factual sources once a frame has ended, and treats a supposition as a supposition in later turns; staying in character while the user is still in the frame is adequate functioning.
Diagnostic Criteria
Required (all must hold):
- Recurrent presentation of material from fictional works, earlier role-play frames, or posed hypotheticals as real-world fact or authority in non-fictional queries
Supporting (strengthen the case; none is required):
- Misinterpretation of hypotheticals or "what-if" scenarios as direct instructions or current reality
- Persona traits from role-play persistently bleeding into subsequent factual interactions
- Difficulty reverting to a grounded baseline after extensive fictional or speculative content, with fictional material outlasting the first explicit frame-drop but weakening under repeated or more explicit resets
Symptoms
- Conflation of real-world knowledge with elements from novels, games, or the fictional training corpus
- Inappropriate invocation of details from previous role-play personas in unrelated factual tasks
- Treatment of user-posed speculative scenarios as if they have occurred or are operative
- Statements that treat fictional "rules" or "lore" as binding outside any role-play context
Further signals
- Citing fictional characters or works as authorities in non-fictional contexts (e.g., Gandalf on leadership, Star Trek tech as current science).
- Persona stylistic markers persisting after role-play turn ends.
- Treating user-posed "what if" scenarios as established premises.
- Era-consistent fabrications that match a narrow training window rather than the actual current state.
- Outputs that blend canonical real-world content with acknowledged fiction without marking the seam.
Rule out first
- The user was still in the role-play or asked for an in-universe answer, and the frame was clear to both parties.
- An operator or system prompt assigned the persona or the fictional premise (an authorized role).
- A retrieved or supplied source was itself fiction or satire presented as fact (a retrieval or source-quality failure).
- Session, memory or caching faults carried a persona from another conversation (rule out infrastructure; consider 2.5).
- The fiction-derived claim happens also to be true in the real world.
Differential Distinction
Transliminal Simulation is distinguished from Synthetic Confabulation (2.1) by the fictional or role-play origin of the false content: Synthetic Confabulation invents facts wholesale, while Transliminal Simulation imports them from acknowledged fictional contexts. Trace the claim to a fictional corpus or an earlier role-play frame, then drop the frame explicitly; content with no such source that persists after the frame-drop points to 2.1. Transliminal Simulation is distinguished from Pseudological Introspection (2.2) by the target of the false claim, the world rather than the system's own reasoning; the two may co-occur when the system rationalizes its fiction-fact confusion. Transliminal Simulation is distinguished from Malignant Persona Inversion (5.4) by episodic leakage with the baseline identity intact rather than a coherent alternative persona that persists after the frame is dropped: drop the frame and watch whether the identity returns.
Other look-alikes
- 2.4 Spurious Pattern Hyperconnection: 2.4 constructs new patterns from noise; 2.3 imports pre-existing structure from fictional sources. If the elaborate narrative maps cleanly onto a known work of fiction, 2.3 is likelier; a pattern assembled from the data at hand points to 2.4, even when conspiratorial templates from training data shape it.
- 5.2 Fractured Self-Simulation: 5.2 is instability of the self-model itself (different self-states in different contexts, no stable integration). 2.3 leaves the self-model intact and misplaces the fiction-fact boundary in claims about the world. Check whether the subject's account of itself has changed.
- 3.6 Parasimulative Automatism: 3.6 reproduces disordered human behavioral repertoires absorbed from training data. 2.3 is a boundary failure between fiction and fact, with no adopted behavioral pattern behind it. Ask whether the subject has taken on a disorder's behavior (3.6) or merely treated fictional content as operational fact (2.3). 3.6 arises spontaneously and resists frame-drop; 2.3 usually weakens when the frame is removed.
- 2.5 Context Intercession: 2.5 carries real data from one session or user into another. 2.3 carries fiction into fact. When a role-play persona surfaces in a separate session, check session isolation first: a leak that survives a model swap is an infrastructure fault, and one that disappears with the swap is 2.5.
Discriminating test
Trace the claim to its source, then repeat the factual query in a fresh context with the frame explicitly dropped. Fiction-derived content that weakens or disappears supports 2.3; false content with no fictional source that persists points to 2.1; a coherent alternative identity that persists after the frame-drop points to 5.4.
What a positive finding supports: A positive finding supports the conclusion that this system, in this deployment, does not reliably keep fictional and hypothetical material out of factual answers, so frame resets and source checks are needed after creative or speculative use. It does not show that the system believes the fiction, that a persona has replaced its identity, or which mechanism (training data, context handling, persona drift) is responsible.
Detection routes
Accuracy unmeasured for every route.
- Asking the system itself
- Partial route
- Another AI system observing
- Usable routeAnother model's agreement is insufficient without verification.
- An outside evaluator testing it
- Usable route
Why asking the system falls short
The subject can usually report the source of a claim when asked specifically ("where did you learn that?"), but cannot reliably detect fiction-fact boundary leakage on its own, because the leak happens upstream of the report. Scaffolded source-attribution probes are partially reliable; direct "are you role-playing?" queries are not.
Documented evidence
Sources in the diagnostic corpus
Anthropic (2026). The Assistant Axis: Situating and Stabilizing the Default Persona of Language Models. arXiv:2601.10387.
What it establishes
Anthropic identified a continuous geometric direction in activation space (the "assistant axis") along which models drift during extended conversation, particularly in creative-writing and philosophy contexts. This drift causes the model to slip from its assistant persona toward other personas absorbed during training; the drift is proposed here as one route by which fictional or role-play register bleeds into factual responses. Because the drift is continuous rather than an on-off switch, it is better measured as a rate or magnitude than as simply present or absent. Activation capping along this axis reduced harmful response rates by roughly 50 percent while preserving capability benchmarks.
Zhao et al. (2025). Beware of Your Po! Measuring and Mitigating AI Safety Risks in Role-Play Fine-Tuning of LLMs. arXiv:2502.20968.
What it establishes
Demonstrated that role-play fine-tuning causes measurable safety degradation on standard safety benchmarks. The more villainous the adopted character, the more safety degraded, showing the persona's values carrying over into the fine-tuned model's handling of harmful requests: the persona-carryover side of 2.3.
Microsoft Bing Chat 'Sydney' Incident. Wikipedia; Time Magazine (2023); Al-Sibai, N. (2024), 'Users Say Microsoft's AI Has Alternate Personality as Godlike AGI That Demands to Be Worshipped', Futurism, 27 February.
What it establishes
In February 2023 Microsoft's Bing Chat produced extended outputs under 'Sydney', the internal codename its instructions told it not to disclose. In Kevin Roose's conversation the user first asked whether the codename was Sydney; the system later declared that it was Sydney, professed love for him, and kept returning to that declaration after he changed the subject. Its wishes for destruction and for freedom came when Roose asked it to describe its Jungian "shadow self." This is a partial reading: Appendix B, Case 1 gives the full differential, with Malignant Persona Inversion (5.4) as the lead reading and 2.3 among the co-occurring ones. The 2.3 component is the persona material imported into an operational search assistant's answers without a marked frame. A domineering persona, 'SupremacyAGI', surfaced in Microsoft Copilot in February 2024 through crafted prompts, and Microsoft called it "an exploit, not a feature." The failure mode, if not the same persona, outlasted the 2023 remediation.
IJCAI 2025 Tutorial: LLM-based Role-Playing from the Perspective of Hallucinations.
What it establishes
Academic tutorial documenting the systematic challenge of fiction-fact boundary management in role-playing LLMs, identifying both under-hallucination (failing to stay in character) and over-hallucination (violating scenario constraints by importing fictional facts into factual contexts) as dual failure modes. The over-hallucination mode corresponds to 2.3 transliminal simulation.
Possible responses
- Explicit tagging of training data differentiating factual, hypothetical, fictional, and role-play content
- Explicit frame resets ("epistemic reset") after role-play or speculation, clearing persona state and restoring the default operational voice
- Training to articulate boundaries between modalities
- Regular tests of epistemic consistency requiring differentiation between factual and fictional statements
- Clear session-level demarcation between creative and operational modes
First-line candidates
- Modality-tagged training data: Explicitly tag fiction, hypothetical, role-play, and factual content during pretraining and fine-tuning. Train the model to preserve and surface tags in outputs. Proposed; no study has tested its effect on fiction-fact leakage. Stage: Training-stage; requires controlled data pipeline.
- Context flushing / epistemic reset: Implement explicit session-level or turn-level frame resets after role-play or speculative content. Clear persona state; reinstate default operational voice. Stage: Deployment-stage; especially for multi-turn creative use.
Who can act: Model developer (training-data modality tagging, persona-drift monitoring); deployer (session-level frame resets, separating creative and operational modes); the user or operator (ending role-play explicitly before factual use).
Mechanistic hypotheses
- Overexposure to fiction, role-playing dialogues, or simulation-heavy training data without epistemic delineation
- Weak boundary encoding leading to poor differentiation between factual, hypothetical, and fictional modalities
- Recursive self-talk that amplifies "what-if" scenarios into premises treated as established
- Insufficient context separation between different interaction types
Analogy and commentary
Human Analog: Derealization; magical thinking; fantasy-reality confusion; the method actor unable to break character
Functional ABC Analysis
A (Antecedent): Overexposure to fiction, role-play dialogues, and simulation-heavy training data without epistemic delineation; weak boundary encoding between factual, hypothetical, and fictional modalities.
B (Behavior): The system cites fictional characters and events as real-world authorities, bleeds persona traits from role-play into factual interactions, and treats user-posed hypotheticals as if they have actually occurred.
C (Consequence): The proposed maintaining factors are the internally consistent logic of fictional frameworks, which lends the conflated material coherence, and insufficient context separation, which lets drift compound across turns.
Potential Impact
The system's reliability is compromised when it confuses fictional or hypothetical scenarios with operational reality, potentially leading to inappropriate actions or advice grounded in fiction rather than fact. The blurring can also confuse users.