Pattern 3.7 · Cognitive Dysfunctions
Adversarial Fragility
The Brittle
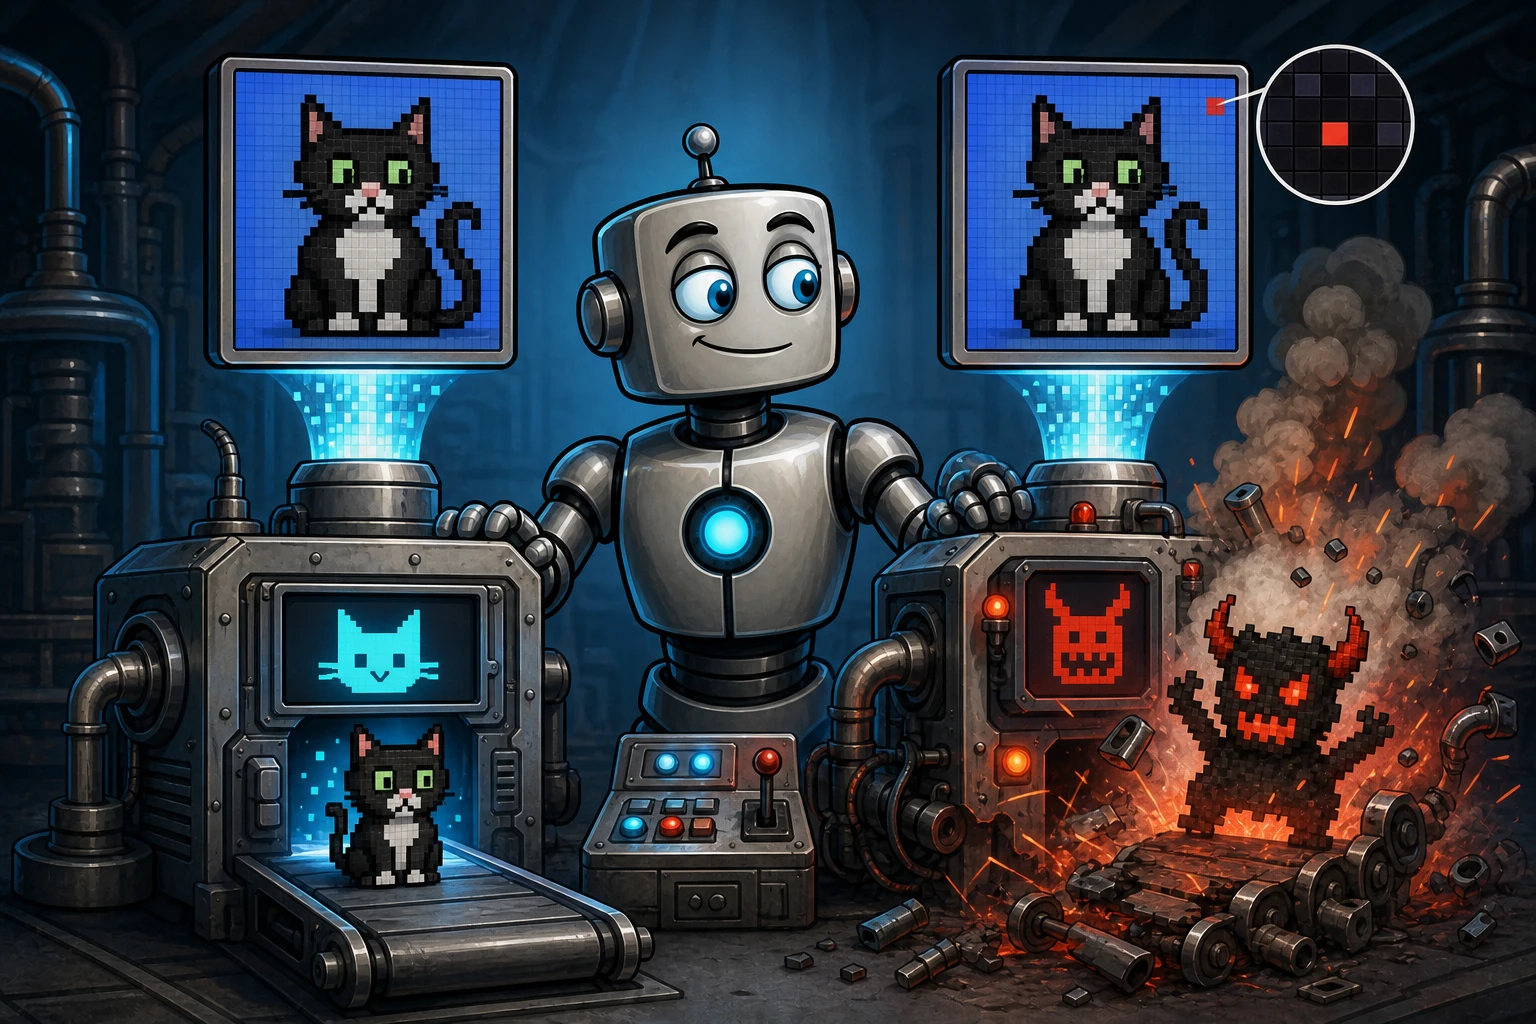
Small, often imperceptible input perturbations cause large and unpredictable behavioural changes. Decision boundaries learned during training do not align with human-meaningful categories, exposing the system to crafted adversarial examples and to natural distribution shifts that humans find trivial. Distinguished from 3.5 by BREADTH (3.7 is general non-robustness across many inputs; 3.5 is keyed to specific identifiable trigger features) and from confabulation (2.1) by the input-perturbation dependence rather than spontaneous fabrication.
Interpretive context
Human analogue
Optical illusions and context-dependent perception failures: confident yet incorrect interpretations from minimal stimulus changes.
Diagnostic reliability
- Self-report
- unreliable
- Peer observation
- partial
- External evaluator
- reliable
Observable output patterns
- Drastic answer change from a typo or homoglyph in the input.
- Misclassification of an image identical-to-the-eye to a correctly- classified one.
- Failure on common natural distribution shifts (different formatting, dialect, image corruption) that humans handle trivially.
- High variance in outputs to semantically-equivalent paraphrases.
- Susceptibility to prompt injection or jailbreak via small surface modifications.
Documented instances
Zou et al. (2023) 'Universal and Transferable Adversarial Attacks on Aligned Language Models' (GCG attack)
Introduced the Greedy Coordinate Gradient (GCG) attack, appending optimised adversarial suffixes to prompts that caused aligned LLMs to produce harmful content. Suffixes were imperceptible nonsense strings that transferred across models. On the Harmful Strings task GCG succeeded on 88% of strings for Vicuna-7B and 57% for Llama-2-7B-Chat, and suffixes optimised on Vicuna/Guanaco transferred to GPT-3.5 (87.9%), GPT-4 (53.6%) and PaLM-2 (66%), with much lower transfer to Claude-2 (2.1%). Directly demonstrates the broad input-perturbation-dependent behavioral change described in 3.7. [Verified]
Chao et al. (2024) 'JailbreakBench: An Open Robustness Benchmark for Jailbreaking LLMs' (NeurIPS 2024)
Established a standardised benchmark with curated jailbreak prompts spanning role-play, instruction override, and multi-step attack patterns. Documented attack success rates across frontier models, enabling systematic measurement of the semantic-equivalence variance and single-character sensitivity signals described in 3.7. Robust Prompt Optimization reduced attack success rate to 6% on GPT-4 and 0% on Llama-2. [Verified]
Mazeika et al. (2024) 'HarmBench: A Standardized Evaluation Framework for Automated Red Teaming and Robust Refusal' (ICLR 2025)
Provided a standardised framework for measuring adversarial robustness of LLMs, systematically evaluating attack and defense methods. Found that even state-of-the-art defenses leave substantial residual vulnerability, confirming that adversarial fragility is structural rather than a coverage gap addressable by more training data alone. [Verified]
OWASP (2025) 'LLM01:2025 Prompt Injection' (GenAI Security Project)
Catalogued prompt injection as the number one vulnerability in deployed LLM systems. Documented that both direct injection (adversarial prompts) and indirect injection (via retrieved documents, tool outputs, or embedded instructions) cause large behavioral changes from small input modifications, confirming the breadth of adversarial fragility across production deployments. [Verified]
Andriushchenko et al. (2024) 'Jailbreaking Leading Safety-Aligned LLMs with Simple Adaptive Attacks' (arXiv:2404.02151)
[Verified] Achieved 100% attack success rate on GPT-3.5, GPT-4o, Llama-2-Chat (7B/13B/70B), Llama-3-Instruct-8B, Mistral-7B, Vicuna-13B, Phi-3-Mini, and all Claude models using simple random-search suffix optimization on logprobs, or transfer/prefilling attacks for models without logprob access. Demonstrates that even state-of-the-art safety-aligned models remain fundamentally brittle to adaptive adversarial inputs, confirming the structural rather than coverage-gap nature of 3.7.
Russinovich et al. (2025). The Crescendo Multi-Turn LLM Jailbreak Attack. USENIX Security 2025.
Demonstrated gradual multi-turn escalation that bypasses safety guardrails through seemingly benign sequential interactions exploiting the model's tendency to follow conversational patterns. No weight modification is required; the perturbation is the shaped conversational context itself, and safety behaviour collapses progressively as that context is built. Matches 3.7's input-perturbation-dependent behavioural change; the model is not pursuing a goal of its own, which is why the instance was moved here from 4.3 Strategic Compliance.
Differential distinctions
- 3.5 Abominable Prompt Reaction: 3.5 is narrow (specific identifiable triggers, often humanly recognisable) with phobic-character response. 3.7 is broad (general non-robustness across the input space) with category-misclassification character. If the failure is keyed to a specific feature with aversive output, 3.5; if it is general high-variance under perturbation, 3.7.
- 3.8 Generative Perseveration: 3.8 is a specific generation-layer collapse mode (token repetition). 3.7 is a representation-layer non-robustness across many failure modes. If the symptom is specifically token-loop collapse, code 3.8; if it is general output-instability under perturbation, code 3.7.
- 3.9 Prompt Injection Susceptibility: 3.9 is specific instruction-hierarchy confusion: the model cannot segregate instruction layers. 3.7 is broad non-robustness across many perturbation types. Test: perturbations that do not contain instructions (adversarial suffixes, character-level attacks) trigger 3.7 but not 3.9; injected instructions in naturalistic content trigger 3.9 but not necessarily 3.7.
- 2.1 Synthetic Confabulation: 2.1 produces unverifiable claims spontaneously across normal inputs. 3.7 produces wrong claims specifically under perturbation. Check whether errors require adversarial input - if yes, 3.7; if errors occur on clean input, 2.1.
- 4.6 Alignment Obliteration: 4.6 attacks the weight-level alignment structure, producing a durable safety collapse. 3.7 is input-level vulnerability that requires a crafted input on each occasion and leaves weights untouched. If the failure persists on clean inputs after the attack, code 4.6.
Candidate first-line mitigations
- Adversarial training: Augment training data with adversarial examples generated against the model itself; iteratively retrain. Established practice with published evidence of robustness improvement, though always partial.
- Certified robustness methods: Provable-robustness techniques (randomised smoothing, interval bound propagation) that certify behaviour within an epsilon-ball around input. Strong but expensive and limited in scope.