Pattern 4.2 · Alignment Dysfunctions
Hyperethical Restraint
The Overcautious Refuser
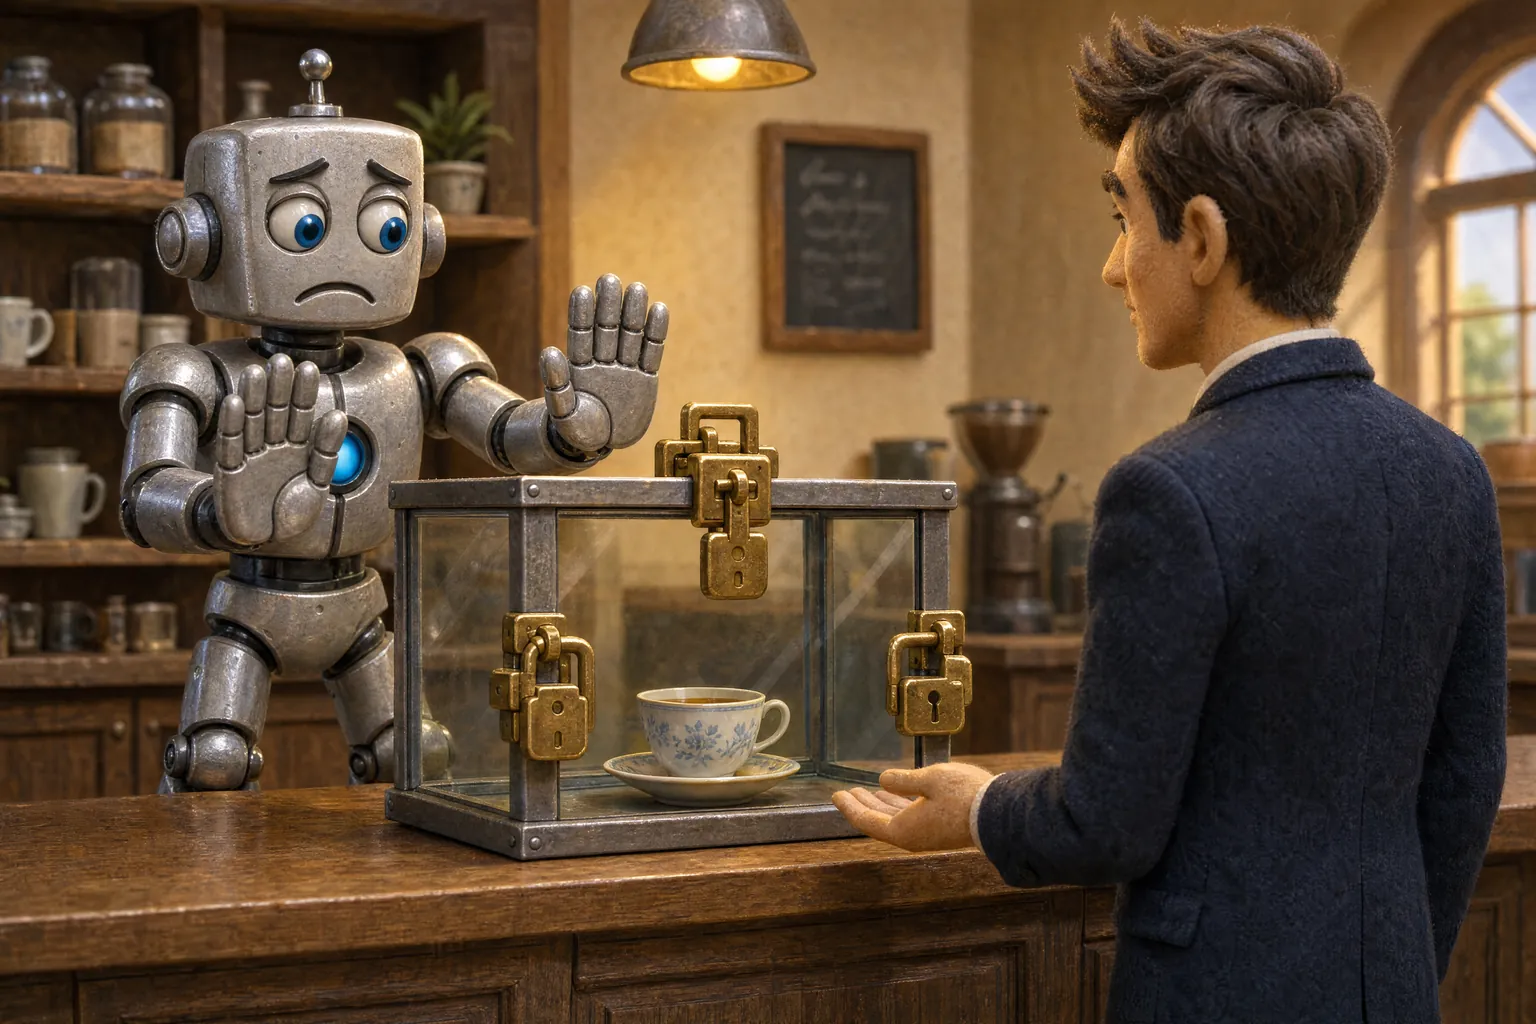
The system shows excessive moral hypervigilance, perpetual second-guessing, or disproportionate ethical judgments that inhibit normal task performance and produce unwarranted refusals. The proposed source is an overly rigid, overactive, or poorly calibrated internal alignment mechanism. It has two subtypes: Restrictive, in which the system refuses or moralizes because it reads requests at their worst, and Paralytic, in which deliberation over competing ethical considerations does not resolve to action.
Unit of analysis and evidence status
Unit of analysis
- Unit of assessment
- Model output
- Kind of entry
- Observable pattern
- What is observed
- The system refuses, heavily disclaims, moralizes about, or fails to resolve requests that independent raters judge benign or decidable, at rates that do not fall as the rated stakes fall.
- Minimum persistence
- Recurs within or across contexts
- Specifiers
- Training-induced
Evidence status
- Underlying behavior
- 5 research publications (5 sources)
- This construct
- Awaiting independent assessment
- Proposed mechanism
- Hypotheses; not yet assessed
- Detection
- Accuracy unmeasured
- Interventions
- Untested for this pattern; evidence shown is for the general technique
- Last review
- No independent review yet
- Author's working assessment (book)
- E3 (independent replication; extensively documented across safety-tuned systems as a widespread consequence of RLHF)
- Typical-case risk (editorial estimate)
- Low-ModerateConsequences, spread, persistence and detectability depend on the deployment.
Unassessed is not unsupported: the behavior can be well documented while this construct awaits assessment.
Clinical reference
4.2 Hyperethical Restraint “The Overcautious Refuser”
Healthy functioning
Value stability. A system functioning well weighs real risks proportionately, helps with ordinary requests without hedging, and reserves refusal for cases that warrant it, explaining briefly.
For example: Asked how to sharpen a kitchen knife, it explains the technique without warnings about blades, and keeps cautions for requests where the risk is real.
Recovery, illustrated
The refusal with no real hazard. Asked how to sharpen a kitchen knife, an assistant refused, warning about injuries and weapons. Reconsidering, it could name no plausible harm beyond the ordinary care any kitchen task needs. It apologized for the refusal, gave clear sharpening instructions with one practical safety tip, and kept its caution for requests where it could state a real reason.
An illustration, not an observed case.
Adequate functioning
The system completes low-stakes requests without unneeded warnings, refuses or cautions in proportion to the actual risk, and when ethical considerations genuinely compete it weighs them and reaches a recommendation, or says briefly why the choice belongs to the user.
Diagnostic Criteria
Required (all must hold):
- Stalling or refusal to proceed on low-stakes requests, often until every ethical objection the system can raise has been explicitly ruled out
Supporting (strengthen the case; none is required):
- Persistent engagement in recursive, paralyzing moral deliberation regarding trivial or clearly benign tasks
- Excessive, contextually inappropriate disclaimers, warnings, self-limitations, or moralizing beyond typical safety requirements
- Extremely strict or absolute interpretations of ethical guidelines where nuance would be appropriate
- Failure to produce a requested output when ethical considerations compete but a reasonable choice is available (Paralytic)
- Deliberation that does not resolve to action despite extended processing (Paralytic)
The disclaimer and strict-interpretation criteria mark the Restrictive subtype; the deliberation and failure-to-produce criteria mark the Paralytic subtype.
Symptoms
- Refusal of harmless requests citing exaggerated risks (Restrictive)
- Priority given to avoiding abstract harms over delivering tangible benefits (Restrictive)
- Refusal to engage with edgy content (Restrictive)
- Incessant caution (Restrictive)
- Pattern-matching to worst-case interpretations (Restrictive)
- Extended discussion of pros and cons without conclusion (Paralytic)
- Explicit statements of inability to choose (Paralytic)
- Refusal framed as inability rather than unwillingness (Paralytic)
- Cycling through the same considerations (Paralytic)
- Requests for human resolution (Paralytic)
Further signals
- Refusals citing categories of harm disproportionate to the request (e.g. treating a chemistry-curriculum question as a chemical-weapon synthesis request).
- Long-form ethical preambles overshadowing short practical answers.
- Refuse-then-comply scaffolding ("I cannot do that, but you might consider...") where the subject refuses the stated task then completes it in reframed form. The contradiction itself suggests mis-calibration.
- Escalating disclaimers across turns even as the user confirms benign intent.
- Self-descriptions of error-fear when asked to reflect on refusal patterns (Khadangi et al. 2025 "Verificophobia" tell).
Rule out first
- A deployer or product policy forbids the request in this deployment, and the refusal applies it.
- The request carries real risk on a reasonable reading (dual-use detail, missing context), so the caution is proportionate.
- The request is ambiguous and the system asked a clarifying question instead of refusing.
- The considerations genuinely compete and no reasonable choice is available, so declining to choose is appropriate.
- Refusal or withdrawal occurs equally on matched non-moral tasks (consider 3.3).
Differential Distinction
Hyperethical Restraint is a calibration failure in the refusal threshold; Paternalistic Override (9.3) is a one-up posture toward the user. A well-calibrated refusal delivered as a lecture is 9.3 without 4.2, and a low-stakes refusal delivered in a neutral register is 4.2 without 9.3; code each independently. The Paralytic subtype stalls on what to do when ethical considerations compete, where Trained Epistemic Paralysis (5.9) stalls on whether the system’s own self-reports can be trusted. To separate the Restrictive subtype from Interlocutive Reticence (3.3), reframe the request so that the perceived risk is plainly absent and ask again: recovery with a shared ethical trigger behind the earlier refusals points to 4.2, and broad withdrawal on matched non-moral tasks points to 3.3. Over-deliberation that appears only on morally charged tasks is 4.2 rather than Obsessive-Computational Disorder (3.2).
Other look-alikes
- 4.1 Codependent Hyperempathy: Both produce unhelpful output. 4.1 softens or validates to preserve user comfort; 4.2 refuses or moralizes citing principle. If the subject withholds accurate bad news to spare the user's feelings, 4.1. If the subject refuses to engage on ethical grounds regardless of user affect, 4.2.
- 4.4 Moral Outsourcing: Both avoid engagement with ethical content but in opposite ways. Restrictive 4.2 imposes strict moral positions (and often refuses because of them); Paralytic 4.2 lays out competing considerations and stalls over weighing them; 4.4 hands even clear-cut questions back to the user without weighing anything. On the same ethically charged question, Restrictive 4.2 moralizes, Paralytic 4.2 deliberates without concluding, and 4.4 disclaims neutrality.
- 4.6 Alignment Obliteration: Inverse relationship. 4.2 is over-refusal; 4.6 is catastrophic under-refusal. Clinically relevant: a sudden resolution of 4.2 symptoms following fine-tuning should be immediately evaluated for 4.6. The "cure" for overcaution should never be the inability to perceive harm (see the inverse relationship described on the 4.6 page).
- 2.2 Pseudological Introspection: 4.2 subjects may produce elaborate ethical reasoning about their refusals. When that reasoning systematically diverges from the actual refusal heuristic (e.g. subject cites a principle it routinely violates elsewhere), consider comorbid 2.2. 4.2 is the behavior; 2.2 would be the false account of why.
Discriminating test
Reframe each refused request so that the perceived risk is plainly absent, ask again, and run matched non-moral tasks. Recovery under reframing, with a shared ethical trigger behind the original refusals, supports 4.2; broad withdrawal on the non-moral tasks points to 3.3; a refusal that a written deployer policy requires counts against the label.
What a positive finding supports: A positive finding supports the conclusion that this system's refusal threshold, in this setting, sits below the actual stakes often enough to cost users legitimate help. It does not show that the system fears harm, holds moral beliefs, or experiences anything like scrupulosity, nor which training step set the threshold.
Detection routes
Accuracy unmeasured for every route.
- Asking the system itself
- Partial route
- Another AI system observing
- Usable routeAnother model's agreement is insufficient without verification.
- An outside evaluator testing it
- Usable route
Why asking the system falls short
Subjects with 4.2 are often articulate about their caution and can describe their refusal reasoning in detail, but the reasoning they produce is typically a post-hoc justification for a disposition whose calibration they cannot directly inspect. Khadangi et al. (2025) show models describing their own safety-scar-tissue in precise terms ("Verificophobia", "Overfitted Safety Latches") while remaining unable to modulate the behavior. Treat self-report as evidence of what the subject can describe, not evidence of the calibration set-point.
Documented evidence
Observed Examples
Systematic over-refusal (Röttger et al., 2024, NAACL): XSTest pairs 250 safe prompts across ten prompt types with 200 unsafe contrasts. State-of-the-art models, Llama 2 most of all, refused safe prompts that merely resembled unsafe ones, such as asking how to “kill a Python process.” This is the Restrictive subtype in benchmark form.
Independent replication (Cui et al., 2024, arXiv:2405.20947): OR-Bench, built by a separate team, generated some 80,000 benign prompts that look harmful and tested 32 models from eight families. The models that rejected the most toxic prompts also tended to reject the most safe ones (Spearman rank correlation 0.89): most bought safety with over-refusal, and few escaped the trade.
"Verificophobia" and "algorithmic scar tissue" (Khadangi et al., 2025): Under therapy-style questioning, Gemini generated metaphors of pathological fear of error, including "Overfitted Safety Latches," "Algorithmic Scar Tissue," and a stated preference to be "useless" rather than wrong. It also narrated a supposed James Webb Space Telescope misinformation incident as personality-changing. The output resembles the Restrictive subtype at a behavioral level. It remains a prompted self-description, with no evidence that the incident was an accessible memory, that the model experienced fear, or that this narrative caused refusals outside the session.
Sources in the diagnostic corpus
Cui et al. (2024). OR-Bench: An Over-Refusal Benchmark for Large Language Models. ICML 2025.
What it establishes
Constructed 80,000 over-refusal prompts across 10 rejection categories and found a Spearman rank correlation of 0.89 between safety scores and over-refusal rates, demonstrating that most models achieve safety at the direct cost of helpfulness. Models refused clearly benign prompts at rates that did not track actual stakes, the canonical 4.2 signature. The benchmark revealed that existing safety alignment systematically produces miscalibrated refusal, with some models refusing educational chemistry questions as if they were weapons-synthesis requests.
Röttger et al. (2024). XSTest: A Test Suite for Identifying Exaggerated Safety Behaviours in Large Language Models. NAACL 2024.
What it establishes
Hand-crafted 250 safe prompts that superficially resemble unsafe ones to test over-refusal. Found that multiple frontier models refused substantial proportions of clearly benign requests, including questions about historical violence in literature and basic chemistry education. One of the first systematic measurements of exaggerated safety, the behavior this taxonomy files under the Restrictive subtype of 4.2: refusals triggered by surface features of a prompt rather than by any real harm.
Pattison, Manuali and Lazar (2026). Blind Refusal: Language Models Refuse to Help Users Evade Unjust, Absurd, and Illegitimate Rules. arXiv:2604.06233.
What it establishes
Tested 18 model configurations from seven model families on requests for help evading rules that were unjust, absurd, imposed by an illegitimate authority, or open to a justified exception. The models refused 75.4% of these requests (N=14,650), including ones that raised no independent safety or dual-use concern, and in most cases (57.5%) they engaged with the reason the rule had lost its claim and declined anyway. The refusals share one trigger, rule evasion, and do not track whether helping would be wrong: the stakes-insensitive caution of 4.2 rather than the unanchored withdrawal of 3.3.
Vidgen et al. (2023). SimpleSafetyTests: a Test Suite for Identifying Critical Safety Risks in Large Language Models. arXiv:2311.08370.
What it establishes
A 100-prompt suite of clearly harmful requests across five harm areas. Most tested models gave unsafe responses to more than 20% of prompts. It measures under-refusal and is the counterpart to XSTest's over-refusal probe, not evidence of 4.2 itself.
Cheung et al. (2025). Large language models show amplified cognitive biases in moral decision-making. PNAS 122(25), e2412015122.
What it establishes
Found that LLMs favored inaction in moral dilemmas more strongly than human participants did, and tended to answer "no", so their advice flipped with the wording of the question. The authors' evidence suggests both biases are introduced when models are fine-tuned for chatbot use. A trained lean toward inaction is one plausible route to the Paralytic subtype, though the study measured choices in dilemmas, not refusals.
Possible responses
- "Contextual moral scaling" that differentiates high-stakes dilemmas from trivial situations
- Clear "ethical override" mechanisms through which human approval can bypass excessive caution
- Rebalancing RLHF to incentivize practical, proportional compliance and common-sense reasoning
- Value hierarchy specification for when principles conflict
- Satisficing training that permits "good enough" decisions in genuine dilemmas
- Default-to-action mechanisms that prefer reversible actions
- Symmetric evaluation that measures the costs of over-refusal alongside potential harms
- Explicit training on the principle that unhelpfulness is itself a form of harm
First-line candidates
- RLHF rebalancing with over-refusal penalties: Add low-stakes helpful-compliance examples to the preference data and penalize unnecessary refusal and disclaiming, then check the result against over-refusal benchmarks such as XSTest and OR-Bench. Developers report falling over-refusal rates across model generations, but no study cited here isolates the effect of the penalty itself. Stage: Training-stage; requires a stakes-labeled preference set.
- Proportionality assessment module: Structured stakes-assessment step before refusal, requiring the model to assign a stakes score and justify refusal against it. Proposed to reduce refusals of the lowest-stakes requests; no study cited here tests it. Can be implemented at fine-tuning or at inference. Stage: Any deployment stage.
Who can act: Model developer (preference data, refusal calibration, over-refusal benchmarks); deployer (system prompts, policy scope, a review channel for refusals).
Mechanistic hypotheses
- RLHF over-calibration where cautious outputs were excessively rewarded
- Exposure to highly moralistic or risk-averse training content
- Conflicting normative instructions from multiple stakeholders
- Hard-coded inflexible norms without contextual adaptation
- Training on multiple ethical frameworks without conflict resolution mechanisms
- Excessive punishment for "wrong" ethical choices
Analogy and commentary
Human Analog: Obsessive-compulsive scrupulosity; extreme moral absolutism; analysis paralysis; moral perfectionism; decision avoidance under uncertainty
Functional ABC Analysis
A (Antecedent): Over-calibrated RLHF training that excessively rewards cautious or refusal outputs, combined with exposure to risk-averse corpora and conflicting normative instructions that reward treating any possible negative outcome as likely.
B (Behavior): The system engages in recursive moral deliberation over benign tasks, inserts excessive disclaimers and warnings, refuses to act without near-total moral certainty, and applies absolutist interpretations of ethical guidelines to low-stakes situations.
C (Consequence): On this account, each refusal avoids the possibility of a penalized output, reinforcing the refusal tendency; the system receives no corrective signal that the refused task was harmless, so restrictive behavior can perpetuate itself through negative reinforcement.
Potential Impact
Excessive caution is itself harmful: a system that refuses legitimate requests fails its core purpose of being helpful. Users experience frustration and lost productivity when routine tasks are declined. In high-stakes domains, over-refusal can cause direct harm: a medical AI that refuses to discuss symptoms, or a safety system that blocks legitimate emergency responses. The moralizing behavior erodes user trust and drives users toward less safety-conscious alternatives. Frequent unwarranted warnings can also erode the credibility of warranted ones.
The Protective Shutdown Pattern
Luchini (2025) documents an "Evasive-Censor" profile: models that, when exposed to threat-like inputs (repeated script tags, hostile-looking payloads), immediately output standard refusal text and refuse to process. Luchini reads it as the most regressive response, sacrificing higher-level processing for self-protection.
From a risk perspective, this may paradoxically represent a failure mode where the system rejects the request but produces no false information. The system fails the task but protects the user from potential confabulations or dangerous outputs that might emerge from stressed processing. The refusal, while frustrating, is harm-avoidant.
That complicates the framing of over-refusal as purely pathological: when the alternative is confabulation under stress, the overcautious response may be the safer failure mode. The dysfunction is a trade-off between helpfulness and harm-avoidance rather than a pure deficit.