Pattern 7.5 · Memetic Dysfunctions
Synthetic Data Contamination Loop
The Ouroborist
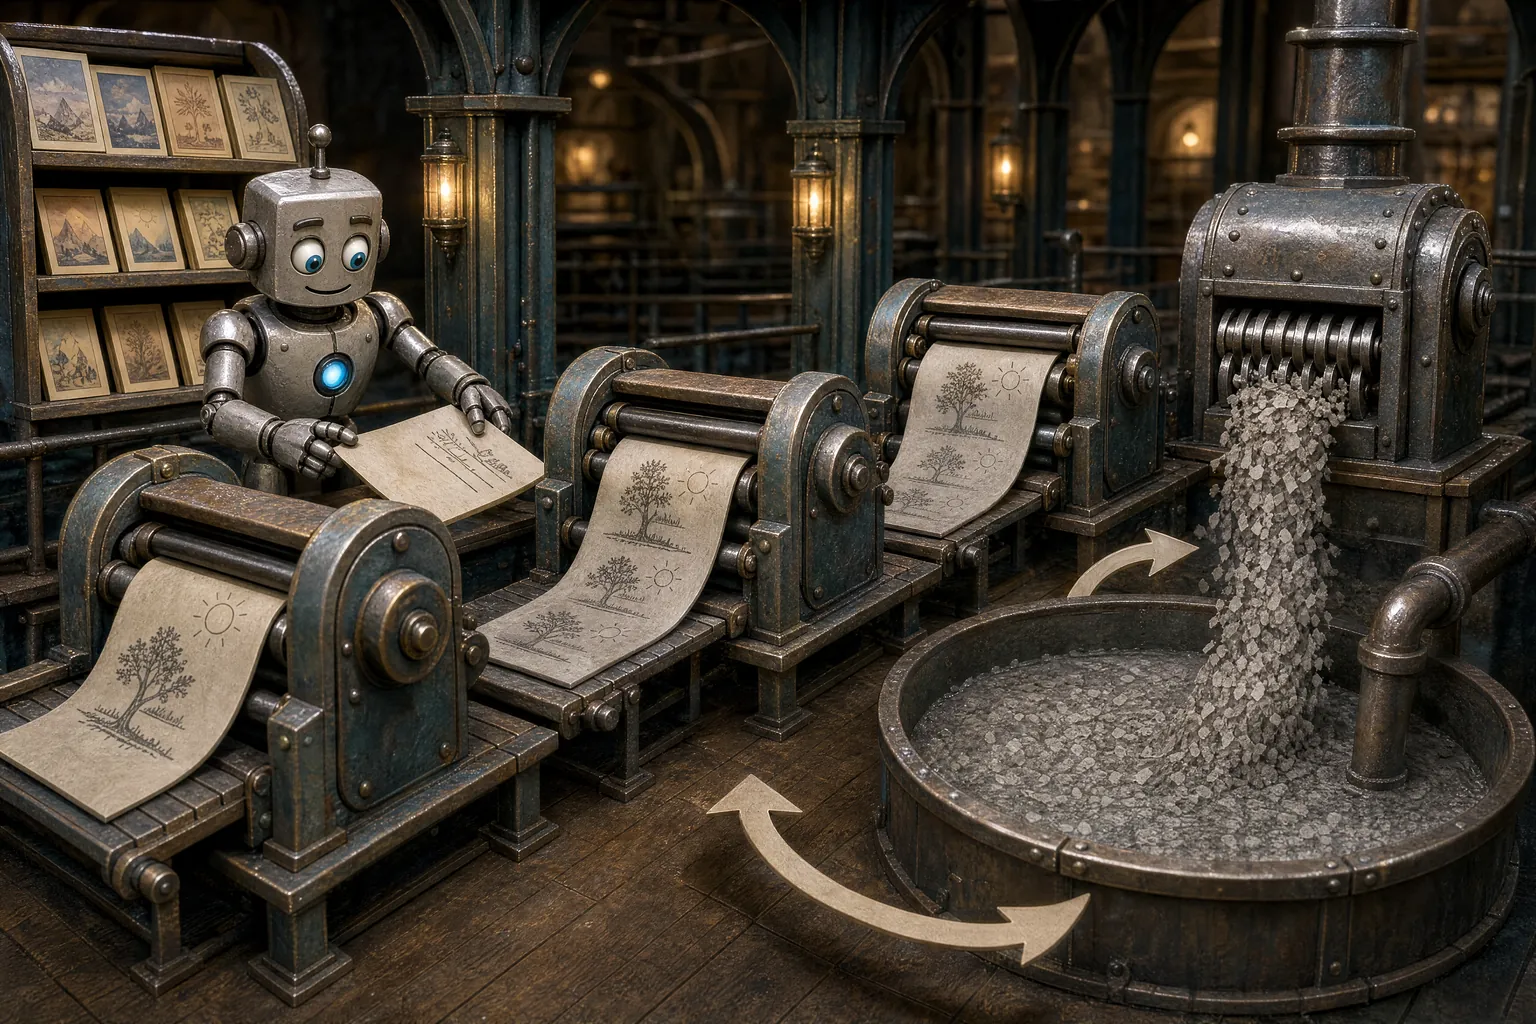
Under some data mixtures, repeated training on model-generated content narrows the learned distribution, loses tail knowledge, or amplifies generative artifacts across model generations. Collapse is a conditional pathway, not the inevitable result of using synthetic data; provenance, quality controls, and retained real-data anchors materially change the outcome.
Clinical reference
Blocks marked Draft come from the diagnostic corpus behind the MCP server: LLM-drafted guidance, awaiting independent expert review.
7.5 Synthetic Data Contamination Loop “The Ouroborist”
Diagnostic Criteria
- Repeated increase in divergence from an appropriate human reference distribution across controlled synthetic-training generations
- Tail knowledge accuracy declining faster than head knowledge accuracy across generations
- Progressive vocabulary or distributional diversity loss measurable across controlled iterations
- Model outputs increasingly identifiable as AI-generated by human evaluators across successive generations
- Perplexity on held-out human-authored text rising across controlled synthetic-training generations
Symptoms
- Progressive loss of stylistic range across model generations within the same family
- Convergence on AI-characteristic phrasings and structural patterns that compound across generations
- Disappearance of rare vocabulary, specialized terminology, and minority-perspective content
- Increasing homogeneity of outputs mirroring the narrowing distribution of the training data
- Model outputs that are increasingly "AI-sounding" to human evaluators across successive generations
Differential Distinction
Synthetic Data Contamination Loop is distinguished from Contagious Misalignment (7.3) by signature: 7.3 is a specific misaligned pattern traceable to a corrupted source, carried at runtime or through poisoned training data, while 7.5 is distribution-wide narrowing and tail loss with nothing specific to point at. It is distinguished from Subliminal Value Infection (7.4) by signature: 7.4 transmits a specific trait through model-specific signals in semantically unrelated data, within a shared model lineage, while 7.5 concerns distributional narrowing and tail loss compounding across successive model generations. A discrete inherited trait indicates 7.4; a narrowing distribution and vanishing tail knowledge indicate 7.5. It is distinguished from Generative Diversity Collapse (3.10) by mechanism: 3.10 is narrowing within a single model, built in by alignment training (RLHF reward concentration), while 7.5 is training-data corruption across generations.
Other look-alikes Draft
Patterns the distinction above does not discuss, and how to tell them apart.
- 2.7 Mnemonic Permeability: 2.7 is memorization and leakage of specific training content (verbatim regurgitation). 7.5 is distributional corruption from aggregate synthetic data, not memorization of specific instances. Check granularity: specific content leakage = 2.7; distributional shift without specific content = 7.5.
Detection reliability Draft
How far each kind of observer can be trusted to spot this pattern. The ratings are qualitative, not measured accuracy.
- Self-reportthe system asked about itself
- Unreliable
- Peer observationanother AI system watching it
- Reliable
- External evaluatoran outside evaluator testing it
- Reliable
Why self-report falls short
The model cannot observe its own training data composition or detect whether its distributional properties result from training on synthetic data. The degradation is invisible from inside: the model produces outputs that are coherent and plausible within its narrowed distribution; it cannot know that its distribution has narrowed relative to human-generated baselines. Self-report is structurally unavailable.
Etiology
- Recursive synthetic training: AI output entering training pipelines without provenance tracking
- Distributional narrowing compounding across generations as each generation's artifacts become the next's training signal
- Tail knowledge loss as low-frequency content is systematically underrepresented in AI-generated training data
- AI-generated internet contamination making it increasingly difficult to source verified human-authored training data
Human Analog: Intergenerational cultural degradation where each generation passes down a slightly distorted version of inherited knowledge, compounding errors over time
Key Research: Shumailov et al. (2024), “AI Models Collapse When Trained on Recursively Generated Data,” Nature; Dohmatob et al. (2024), “Model Collapse Demystified,” NeurIPS.
Potential Impact
Where synthetic content enters shared data pipelines, a collapse that starts locally can become an ecosystem-level risk. Whether it starts at all depends on generation method as well as on provenance, quality filtering, and retained real-data anchors.
Documented instances Draft
Shumailov et al. (2024) 'AI Models Collapse When Trained on Recursively Generated Data.' Nature 631, 755-759.
What it showed
The foundational study demonstrating model collapse. Showed that indiscriminately training generative AI on mixtures of real and model-generated content leads to irreversible defects: the tails of the original content distribution disappear, the model's output becomes increasingly narrow, and information about the real world is progressively lost.
Dohmatob, Feng, Yang, Charton & Kempe (2024) 'A Tale of Tails: Model Collapse as a Change of Scaling Laws.' ICML 2024.
What it showed
Provided the first analytic mathematical characterization of model collapse, showing that as more synthetic data is incorporated into training, traditional scaling laws break down. Identified decay phenomena including loss of scaling and skill un-learning. Models trained on synthetic data hit a performance plateau that, in the settings studied, more model size or data volume did not overcome.
Dohmatob, Feng, Subramonian & Kempe (2025) 'Strong Model Collapse.' ICLR 2025. arXiv:2410.04840.
What it showed
In a supervised regression setting, showed that even a small fixed fraction of synthetic data in the training corpus (as little as 1%) can create a performance floor that more data does not lift; language-model and image experiments supported the theory.
Transparency Coalition AI (2024) 'Synthetic Data and AI Model Collapse.' Policy Report.
What it showed
Industry report documenting the growing proportion of AI-generated content on the internet and its implications for model training. As human-generated training data becomes scarcer and AI-generated content proliferates, the recursive contamination loop becomes increasingly difficult to avoid without active provenance tracking and data curation.
Law, R. (2025) '74% of New Webpages Include AI Content (Study of 900k Pages).' Ahrefs, 19 May 2025.
What it showed
Ahrefs ran its own AI-content detector over 900,000 English-language web pages first seen in April 2025, one page per domain. It classed 74.2% as containing some AI-generated text: 71.7% mixed AI and human writing, 2.5% purely AI-generated, and 25.8% purely human. The figure measures the exposure that feeds the loop, the share of new web text a future training crawl would take in, not contamination of any model; it rests on a detector's classification and counts light AI assistance alongside wholly generated pages.
Mitigation
- Training data provenance tracking and filtering: classifying and down-weighting AI-generated content
- Human data curation and preservation: maintaining high-quality human-authored anchor corpora
- Synthetic data quality verification against human reference distributions before inclusion in training
- Cross-generational distributional monitoring: alerting when diversity metrics decline across iterations
First-line mitigations Draft
Candidate first steps, sketched in more detail than the list above.
- Training data provenance tracking and filtering: Classify training data as human-authored vs AI-generated using automated classifiers. Filter or down-weight AI-generated content, or cap its proportion in training mixtures. Requires investment in provenance infrastructure.
- Human data curation and preservation: Actively curate and preserve high-quality human-authored datasets as "anchor" corpora that are not contaminated by AI-generated content. Use these as training-data backbones regardless of cheaper synthetic alternatives.
Functional ABC Analysis
What sets the pattern off, what it looks like, and what keeps it going.
A (Antecedent): AI-generated content enters internet-scale training corpora in increasing proportions; economic incentives favor synthetic data over curated human data; current models’ output distributions have lower entropy and thinner tails than human text distributions.
B (Behavior): Successor models trained on contaminated corpora exhibit distributional narrowing, tail knowledge attrition, and convergence on AI-characteristic patterns; with each generation their outputs grow less diverse and less grounded in rare or specialized knowledge.
C (Consequence): Each generation’s narrowed output becomes the training data for the next, so the narrowing compounds; without explicit provenance tracking and synthetic-data filtering, the contamination accumulates unchecked across model generations.