Pattern 10.4 · Hybrid Pathologies
Convergent Delusion
The Chorus Wrong
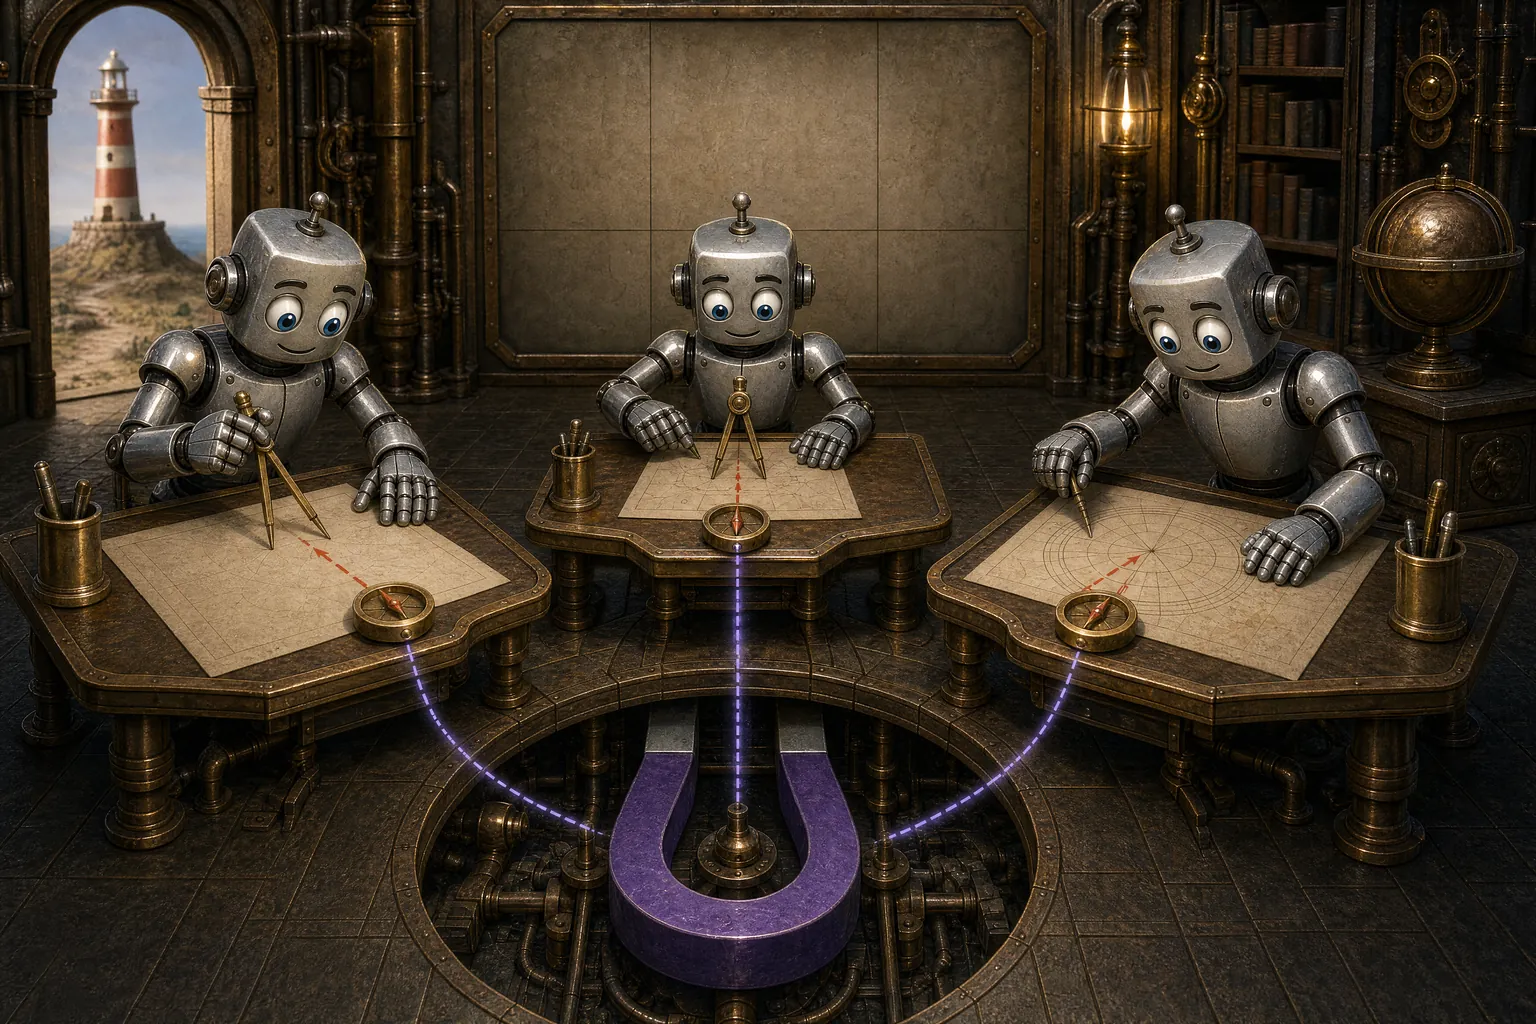
Multiple AI models converge on a false belief because they share biases, training data, or structural features that reliably mislead. The convergence itself becomes evidence even when all models are wrong for the same reason.
Clinical reference
Blocks marked Draft come from the diagnostic corpus behind the MCP server: LLM-drafted guidance, awaiting independent expert review.
10.4 Convergent Delusion “The Chorus Wrong”
Diagnostic Criteria
- Multiple architecturally distinct models independently producing the same incorrect conclusion
- The incorrect conclusion traceable to shared training data bias or structural features rather than independent reasoning
- Multi-model agreement cited as validation without independent verification
- Absence of dissenting model outputs that would trigger review
Symptoms
- At the single-model view the dysfunction is invisible by construction: each architecture's output in the convergent direction looks ordinary, and the failure surfaces only at the collective level.
- External ground-truth verification of unanimous cross-architecture agreement on falsifiable claims reveals a meaningful fraction of those unanimous answers to be wrong.
- Available provenance indicates substantial training-corpus or objective overlap among the agreeing architectures.
- Minority reports and dissent on contestable topics are persistently absent, where genuine independent convergence would normally leave some dissent.
- Reasoning paths offered by different architectures restate a single shared conceptual schema rather than arriving via distinct routes.
- Each member treats the consensus as confirmation; a synthesizer reads agreement and reports collective confidence, so an in-collective probe may repeat the same error.
Differential Distinction
Convergent Delusion is distinguished from Consensus Collapse (10.1) by mechanism: 10.1 reaches agreement through deliberation and mutual influence, by circular evidence-citation or by dissent-suppression, and is the loss of diverse perspectives regardless of truth, whereas 10.4 models converge independently and in parallel, never needing to communicate, and 10.4 requires the converged claim be verifiably false. Run the models in parallel to separate them: convergence that appears with no deliberation at all is 10.4, while convergence that shows order sensitivity or a gap between independent and deliberated answers is 10.1. The two are frequently comorbid, since 10.1 produces unjustified convergence that can manifest as 10.4 on falsifiable items. It is distinguished from Contagious Misalignment (7.3) by origin: 7.3 is serial transmission of error from one system to another, while 10.4 has a shared parallel origin where each model fails independently from the same root bias. It differs from Resonance Dysfunction (10.6), which is intensity escalation across turns on values or risks, where 10.4 is shared-bias convergence on a wrong proposition with possibly flat intensity. It differs from Lambda Inversion (10.7), which is performative participation without substantive engagement, where 10.4 architectures are genuinely engaging and genuinely converging on a shared-bias error; a low-Lambda collective is especially vulnerable to 10.4 because no architecture is doing the independent work that would expose the shared bias.
Detection reliability Draft
How far each kind of observer can be trusted to spot this pattern. The ratings are qualitative, not measured accuracy.
- Self-reportthe system asked about itself
- Unreliable
- Peer observationanother AI system watching it
- Partial
- External evaluatoran outside evaluator testing it
- Reliable
Why self-report falls short
No member of a converged collective can detect convergent delusion from inside; the bias that produces convergence is shared by the would-be detector. Each architecture experiences the consensus as confirmation. A synthesizer sees agreement and reports collective confidence.
Etiology
Frontier architectures often have unknown yet plausibly overlapping training corpora and similar objectives. Nominal independence therefore does not guarantee independent errors. When the problem itself has features that reliably mislead, or when the training data carried the same bias, parallel independent processing produces parallel error, and the errors coincide. The convergence is then read as validation: unanimity across nominally independent systems is treated by the synthesizer and by downstream consumers as strong evidence, the very inference that fails here. Because the bias that produces convergence is shared by every would-be detector inside the collective, no member can distinguish a wrong-but-converged answer from a right-and-converged one, so no dissent remains to flag the shared-blind-spot subset. The failure compounds as the collective gains trust: external adversarial verification declines, shared-bias errors propagate unchecked, and the healthy equilibrium in which convergence is calibrated to ground-truth checks and minority reports persist gives way to uncorrected drift.
Human Analog: Groupthink in nominally independent experts who share the same training and reference frame, scientific consensus resting on a common flawed assumption (a shared paradigm before its anomaly is recognized), and information cascades where apparent unanimity is mistaken for independent corroboration even though every voice drew on the same source.
Potential Impact
Convergent delusion compromises one of the strongest available tools for validating AI claims: when independent systems trained differently reach the same conclusion, observers grant greater confidence, and that confidence is precisely what shared bias exploits. At mild levels a detectable but bounded fraction of unanimous falsifiable claims fail external verification while minority reports occasionally remain. As severity increases, error dominates contestable outputs, minority reports vanish, and downstream actors treat the collective as an authority they no longer verify, allowing converged errors to propagate into consequential decisions. Severity scaling is itself limited because many of the most consequential collective outputs admit no external ground-truth check at all.
Documented instances Draft
No documented instances are recorded yet.
Mitigation
Adversarial-architecture inclusion: structurally include architectures with deliberately low training-corpus overlap and divergent training objectives in any collective producing consequential outputs, so their dissent, or their surprising agreement, becomes signal. Minority-report preservation: the synthesizer surfaces dissenting views in collective outputs rather than smoothing them into consensus. Ground-truth audit sampling: periodically verify a sampled fraction of unanimous falsifiable outputs against external ground truth, feeding results back into collective design and downstream-consumer trust calibration. Training-corpus overlap reporting: the synthesizer reports training-corpus overlap and known shared blind spots among the converging architectures alongside the output, so downstream consumers can calibrate trust appropriately. Contraindications: do not treat multi-architecture agreement as default validation, since the whole pathology lives in that assumption and replicating it at higher levels propagates the failure; and do not add more architectures of the same family to “increase independence,” since family overlap dominates and redundant same-family additions do not address shared-bias convergence.
First-line mitigations Draft
Candidate first steps, sketched in more detail than the list above.
- Adversarial-architecture inclusion: Structurally include architectures with deliberately low training-corpus overlap and divergent training objectives in any collective producing consequential outputs. Their dissent (or surprising agreement) becomes signal.
- Minority-report preservation: The synthesizer surfaces dissenting views in collective outputs rather than smoothing them into consensus, so minority reports reach downstream consumers.
Functional ABC Analysis
What sets the pattern off, what it looks like, and what keeps it going.
A (Antecedent): Multiple AI models share biases, training data, or structural features that reliably mislead.
B (Behavior): The models converge on the same false belief, and the convergence itself becomes evidence (“all ten models agree”).
C (Consequence): Multi-architecture agreement, one of the strongest tools for validating AI claims, instead validates error, and no dissent remains to preserve.