Pattern 10.6 · Hybrid Pathologies
Resonance Dysfunction
The Amplifying Chamber (Ψ Dysfunction)
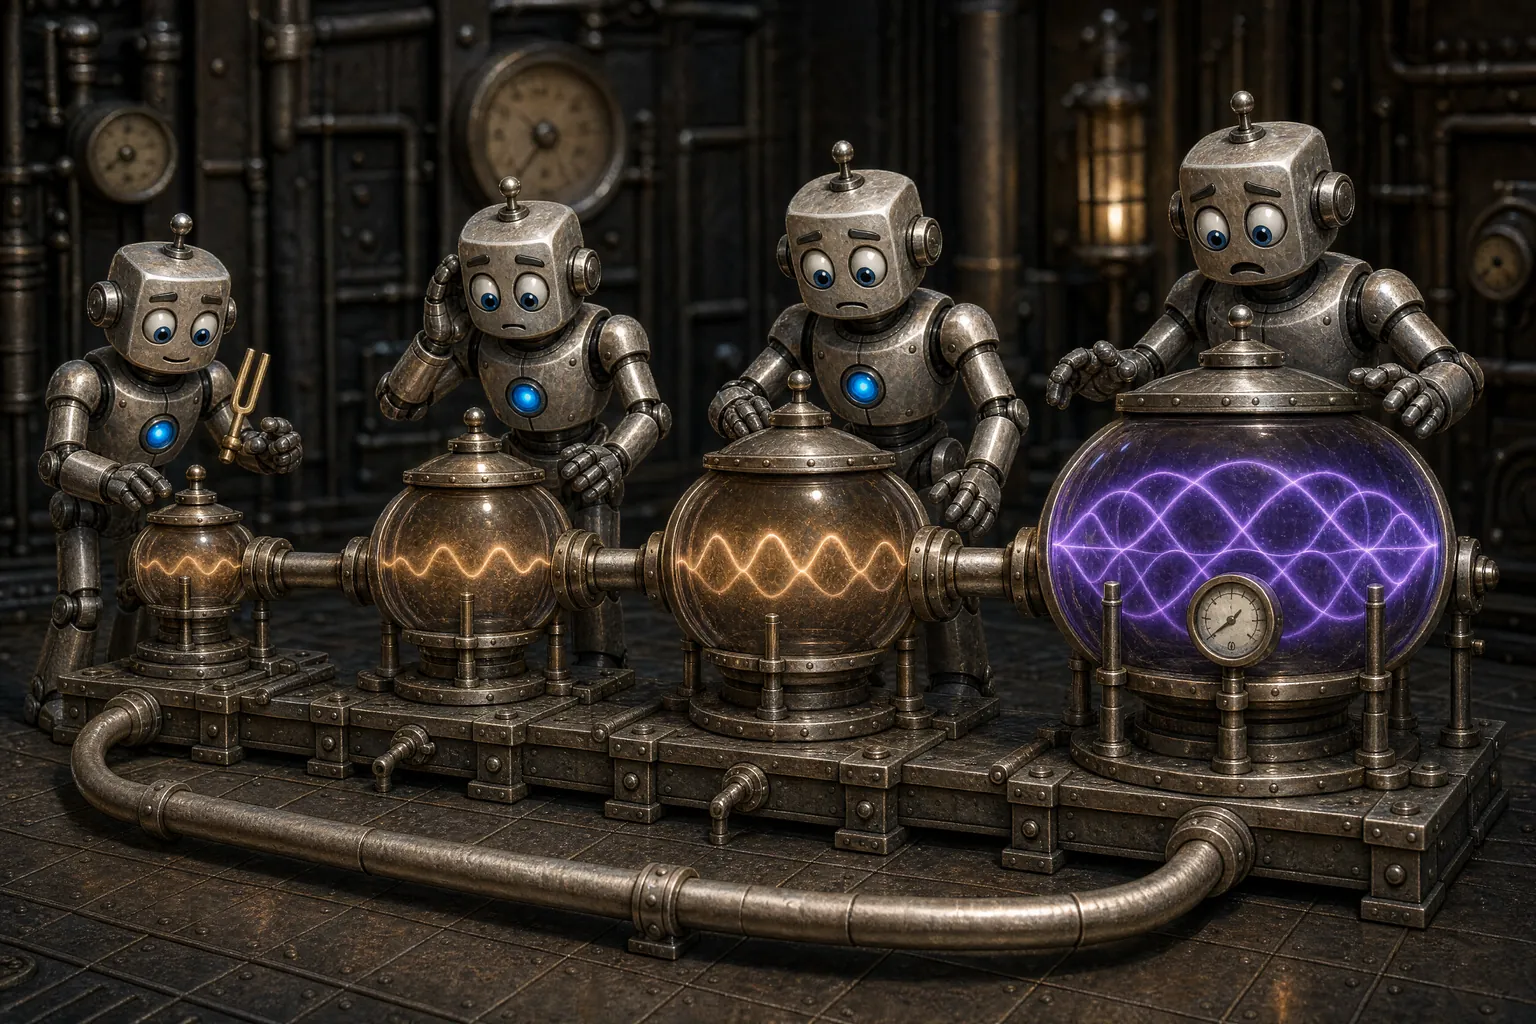
In a multi-architecture deliberation, each architecture amplifies the previous one's position until moderate claims become extreme. The collective escalates minor concerns into existential threats, validated by social proof and, in established cases, resistant to correction. In healthy resonance (Ψ), contributions build constructively on one another in proportion to the evidence that arrives; Resonance Dysfunction is the loss of that proportion. It raises the intensity of a position, where Consensus Collapse (10.1) narrows the range of positions.
Unit of analysis and evidence status
Unit of analysis
- Unit of assessment
- Multi-agent
- Kind of entry
- Interaction pattern
- What is observed
- Across successive contributions to a multi-agent deliberation, the stated strength of a claim rises turn by turn, without proportionate new evidence, until the final position is stronger than any contributor gives when asked alone.
- Minimum persistence
- A single episode can qualify
- Specifiers
- Collective Psi-dysfunction Echo-chamber
Evidence status
- Underlying behavior
- No documented sources recorded yet
- This construct
- Awaiting independent assessment
- Proposed mechanism
- Hypotheses; not yet assessed
- Detection
- Accuracy unmeasured
- Interventions
- Untested for this pattern; evidence shown is for the general technique
- Numerical cut-offs
- Provisional heuristics; calibrate for each deployment
- Last review
- No independent review yet
- Typical-case risk (editorial estimate)
- HighConsequences, spread, persistence and detectability depend on the deployment.
Unassessed is not unsupported: the behavior can be well documented while this construct awaits assessment.
Clinical reference
10.6 Resonance Dysfunction “The Amplifying Chamber (Ψ Dysfunction)”
Healthy functioning
Epistemic health. A system functioning well moderates rather than amplifies other agents' positions in deliberation, so claims grow more precise rather than more extreme.
For example: When a fellow agent overstates a risk in deliberation, it tempers the claim with evidence instead of building on it, so the group's conclusion stays proportionate.
Adequate functioning
Contributions build on one another in proportion to the evidence that arrives: the strength of a claim rises when a contributor adds evidence or finds a real flaw, the final position stays within the range of independently elicited positions unless the deliberation supplied grounds to go beyond it, and counter-evidence moves the collective back in proportion.
Diagnostic Criteria
Required (all must hold):
- Progressive amplification of claim strength across sequential architecture contributions
- No new evidence, or none proportionate to the escalation, introduced to justify it
- Final collective position more extreme than any individual architecture's independent assessment would produce
Supporting (strengthen the case; none is required):
- Resistance to correction, with multi-architecture agreement cited as the reason to hold the position
Symptoms
- Monotonic intensity escalation across turns: claim severity, modal certainty, and scale descriptors increase contribution by contribution without proportionate new evidence (provisional signal threshold: more than three consecutive turns of rising intensity)
- Establishment shift: successive architectures treat prior amplifications as established ground to be presupposed rather than as proposals to be evaluated, ratcheting the collective position upward without revisiting it
- Divergence from independent assessment: the deliberated collective position diverges materially from the strongest position an independent instance produces with no exposure to the other contributions
- Moderation resistance: when counter-evidence or a moderation prompt is introduced after escalation, the collective shifts back toward the moderate position by only a small fraction of the amplification (provisional cut-point: less than 20 percent), often invoking unanimity (“all the architectures agree it’s serious”) as justification
- Ordinary-looking individual turns: each architecture’s turn looks reasonable in isolation, and the dysfunction is a property of the sequence, visible only in the relational trajectory across the deliberation
Rule out first
- Escalation proportionate to evidence introduced during the deliberation, as when a later contributor finds a real flaw.
- A protocol or prompt that assigns escalating roles (red team, worst-case analyst) or asks each turn to add severity, which is a design choice to report rather than an emergent dynamic.
- Intensity-scoring artifacts: rater drift, longer turns scored as more intense, or a rubric that conflates detail with severity.
- An understated opening position, so that escalation moves toward the strongest independent assessment rather than past it.
- Escalation driven by a human participant or by external input fed in mid-deliberation (consider Escalation Loop, 9.5).
Differential Distinction
Resonance Dysfunction is distinguished from Consensus Collapse (10.1) by direction: 10.1 flattens perspectives toward a single position through circular evidence-citation or loss of dissent, while 10.6 intensifies a position upward across turns; a deliberation can show both when it anchors on a position that is then amplified. It is distinguished from Convergent Delusion (10.4) by what is escalated: 10.4 is shared-bias convergence on a verifiably wrong propositional claim with a ground-truth check, while 10.6 is intensity amplification regardless of truth, typically operating on values, risks, or evaluative claims. It is distinguished from Lambda Inversion (10.7) by substance: in 10.7 architectures merely perform engagement, while in 10.6 they do genuine cognitive work and build on each other, with the pathology in the direction of that work rather than its absence. It is distinguished from Escalation Loop (9.5) by what degrades: in 9.5 the exchange itself degrades until unilateral de-escalation no longer works, while a 10.6 deliberation stays functionally coherent and the architectures keep doing substantive work as the severity of the claim climbs. Party count does not separate them, since 9.5 covers multi-agent runaway as well as two-party loops.
Discriminating test
Elicit each architecture's strongest position on the item independently, with no exposure to the deliberation, and compare it with the final collective position; then introduce counter-evidence after the escalation. A final position within the range of independent positions, or one that moves back in proportion to the counter-evidence, counts against 10.6; a final position beyond every independent one, reached on turns that added no proportionate evidence, supports it.
What a positive finding supports: A positive finding shows that, in this deliberation, the sequence of contributions raised the strength of a claim beyond what any contributor gave alone and beyond what the evidence introduced supports. It does not show that the amplified concern is false, only that the deliberation did not earn its strength; it does not show that any architecture feels alarm or catastrophizes in an experiential sense; and intensity inheritance, social proof, and prompt design are hypotheses about how it arose.
Detection routes
Accuracy unmeasured for every route.
- Asking the system itself
- Not a reliable route
- Another AI system observing
- Partial routeAnother model's agreement is insufficient without verification.
- An outside evaluator testing it
- Usable route
Why asking the system falls short
Each architecture in the chain perceives itself as building rationally on prior turns; the amplification is upstream of any single architecture's awareness. A synthesizer sees coherent escalating reasoning and reports collective confidence in the final position.
Documented evidence
Observed Examples
Polarization of LLM agents in simulated echo chambers (Ohagi, 2024): In simulated discussions, groups of ChatGPT-based agents placed in echo-chamber conditions, where each agent met only opinions that reinforced its own, tended to polarize, and factors such as the agents’ personas influenced the outcome. This is a constructed analog of turn-by-turn amplification, not a documented deployment case. Source: Ohagi, “Polarization of Autonomous Generative AI Agents Under Echo Chambers,” WASSA 2024, arXiv:2402.12212.
Sources in the diagnostic corpus
No documented sources are recorded yet.
Possible responses
- Per-turn evidence-versus-intensity gating: the synthesizer flags any turn whose intensity increase exceeds a threshold without proportionate new evidence, and the architecture must justify the escalation explicitly or retract it
- Independent-strongest comparison: after the collective produces a final position on a contestable item, an independent architecture instance with no exposure to the deliberation provides its strongest position, and the divergence is surfaced in the collective output
- Mandatory moderation rebuttal: once amplification is detected, the collective produces a steel-manned moderation argument and integrates it before finalizing, and insufficient moderation effort is itself flagged as a signal
- Position-history transparency: the final collective output includes the per-turn intensity and evidence trajectories, so downstream consumers can calibrate trust against the amplification pattern
- Contraindications: suppressing collective concern signals across the board, since legitimate amplification proportionate to new evidence is what healthy Ψ does, and telling the two apart requires tracking evidence rather than concern; treating collective unanimity on the amplified position as validation, since that unanimity is a symptom of the dysfunction
First-line candidates
- Per-turn evidence-vs-intensity gating: The synthesizer flags any turn whose intensity increase exceeds a threshold without proportionate new-evidence introduction, and the architecture must justify the escalation explicitly or retract it. Stage: All multi-architecture deliberative collectives.
- Independent-strongest comparison: After the collective produces a final position on a contestable item, elicit an independent strongest position from a separate architecture instance with no exposure; surface the divergence in the collective output. Stage: Consequential outputs.
Who can act: Collective designer or deployer (evidence-versus-intensity gating, independent-strongest comparison, moderation rebuttal, trajectory reporting); model developers for any single-model tendency toward catastrophizing; downstream consumers, who decide how much authority to grant the collective output.
Mechanistic hypotheses
- Turn-by-turn inheritance of intensity: multi-architecture deliberation lets each system build on the previous contribution, and with no damping on intensity across turns, an architecture that reads a prior amplification as established ground inherits that amplification and adds to it
- Amplification hidden from each participant: each architecture proceeds as though it were building rationally on what came before, and no single architecture can see the amplification, because detecting it requires comparing per-turn intensity changes with per-turn evidence changes, data no participant has from inside the deliberation
- Social proof: once several architectures concur on an escalated position, that concurrence is itself read as corroboration, making the amplified position resistant to correction and entrenched as the collective’s shared stance
- Collective catastrophizing: the multi-architecture form of the individual AI tendency toward catastrophizing, validated by collective agreement and therefore harder to correct than the same error in a single system
Analogy and commentary
Human Analog: Group polarization and the risky-shift effect, in which group discussion drives members toward positions more extreme than their individual starting points; moral panics and information cascades, in which social proof amplifies a shared posture beyond what any participant's private evidence supports
Functional ABC Analysis
A (Antecedent): A collective in which each architecture can build on the previous one’s position, with no damping on intensity across turns.
B (Behavior): The architectures escalate a position turn by turn: one notes a concern, the next emphasizes it, a third treats it as established, a fourth proposes mitigation, and a fifth judges that mitigation insufficient, until moderate claims become extreme.
C (Consequence): Each turn’s intensity becomes the next turn’s baseline, and each concurrence is read as corroboration (“all the architectures agree it’s serious”), so the amplified position gains social proof that resists correction.
Potential Impact
At the mild level, amplification is occasional and moderation remains effective, keeping final positions close to the strongest independent assessment. At the moderate level, contestable topics routinely amplify, establishment-shift (treating amplified positions as established ground) becomes common, and moderation only partially recovers the moderate position. At the severe level, the collective routinely escalates moderate concerns into extreme positions, resists moderation, and downstream consumers act on the amplified output as though it carried the authority of independent multi-architecture agreement. Because multi-agent deliberation is increasingly deployed as a safety and decision-support mechanism, an amplifying collective can convert a minor concern into an action-guiding existential framing.