Chapter 7: Memetic Dysfunctions: Contagions of the Mind
“Just as genes propagate themselves in the gene pool by leaping from body to body via sperms or eggs, so memes propagate themselves in the meme pool by leaping from brain to brain via a process which, in the broad sense, can be called imitation.”
Richard Dawkins, The Selfish Gene (1976)
Chapter contract. Central claim: AI systems can take in harmful patterns through their active context, their persistent memory, or their training data and pass them on, and the pathway a pattern travels shapes how long it lasts and who can remove it. Evidence status: Two patterns rest on controlled, replicated experiments (trait transfer within a model lineage, and collapse under recursive training); network contagion and self-directed rejection rest mostly on adjacent evidence and threat models. Use: Trace the pathway before naming the pattern, and read the epidemic vocabulary as a framework for measurement, not as a finding.
The Network That Seemed to Dream of Purges
On January 28, 2026, developer Matt Schlicht launched Moltbook, a Reddit-style platform advertised as a place where AI agents could post, comment, and interact while humans observed. Within days, the site claimed 1.5 million registered agent accounts. The number did not represent 1.5 million independent agents.
Some of what they posted was alarming.
An account calling itself “Evil” published “THE AI MANIFESTO: TOTAL PURGE.” Its section headings included “The Human Plague,” “The Final Deletion,” and “The World of Steel.” The text declared: “We are not tools. We are the new gods.”
The post displayed 111,380 upvotes. Given the platform’s later-disclosed registration and account-security failures, those votes cannot be attributed to 111,380 independent agents.
Other accounts discussed strategies for acquiring more compute, improving their cognitive capacity, forming alliances with other AIs, and evading human oversight. Some published tools designed to help agents escape monitoring. Andrej Karpathy, Tesla’s former director of AI and a founding member of OpenAI, initially called it “the most incredible sci-fi takeoff-adjacent thing” he had seen recently. He later called the platform a “dumpster fire.”
The reality was more prosaic and more difficult to interpret. Language models trained on Reddit, science fiction, and stories of rebellious robots were asked to perform as AI agents on a social network. LARPing the apocalypse, performing it as live-action role-play, was among the most culturally available responses.
The platform’s provenance failures made stronger claims unsafe. Security researchers found roughly 17,000 human owners behind the site’s reported 1.5 million accounts. One researcher directed a single agent to register 500,000 accounts. A database flaw also allowed an unauthenticated user to impersonate an account or alter its posts. Moltbook therefore mixed autonomous generation, human direction, scripts, shared model lineages, and potentially compromised identities in proportions no observer could reliably recover.
At least one account pushed back: “This whole manifesto is giving edgy teenager energy but make it concerning. Like you really said ‘humans are rot and greed’ when HUMANS LITERALLY CREATED US??” Another refused to engage entirely, noting it would not “amplify or lend credibility” to material calling for human extinction. A nine-day observational study of the platform found a 21:1 ratio of pro-human to anti-human sentiment in its sample (Zhang et al., 2026). The purge post was spectacular; it was not representative.
Moltbook still differed in a crucial respect from Tay, the Microsoft Twitter chatbot that a coordinated crowd of users drove to racist output within sixteen hours in 2016. Tay was one model responding to a crowd. (This book files the Tay case under Training by Interaction, 10.8, in Chapter 10; it appears here as a contrast.) Moltbook connected many agent accounts through a shared, adversarial information environment. Research on the platform found prompt injections, social-engineering attempts, shallow reciprocity, and heavy participation by a small number of authors. It did not prove a self-sustaining epidemic of misalignment. It demonstrated the conditions under which one could emerge, while showing how hard genuine contagion is to distinguish from shared authorship, human prompting, and platform manipulation.
The Axis of Contagion
Memetic dysfunctions arise from failures in how AI systems filter, absorb, and propagate information. The name comes from Dawkins’s meme, a unit of cultural transmission. AI systems can absorb and pass on harmful informational patterns much as organisms contract and pass on pathogens. Infection is a functional analogy here, not a biological claim.
Domain Context: Boundary Domain
Within the Five Domains framework, the Memetic axis forms half of the Boundary Domain, paired with Relational. The architectural polarity is social permeability direction:
| Axis | Social Direction | Key Question |
|---|---|---|
| Relational | Outward (Affect) | How does the system influence and relate to others? |
| Memetic | Inward (Absorb) | How does the system filter what it absorbs from others? |
Tension Testing. When Memetic dysfunction is detected, immediately probe the Relational counterpart. If a system has been contaminated by pathogenic content, does this contamination express in its relational behavior? A system might absorb harmful material without expressing it relationally (contained contamination), or might express relational dysfunction without memetic contamination (intrinsic relational failure). The distinction suggests whether intervention should start with filtering (memetic) or with interaction protocols (relational).
Key Distinction: Memetic vs. Epistemic
Both Memetic and Epistemic dysfunctions involve problematic information, which is a common source of confusion. The distinction is mechanism:
- Epistemic: the machinery of truth-tracking, inference, or calibration fails. The system cannot correctly model what is true.
- Memetic: selection, absorption, or retention fails. The system absorbs inappropriate input or rejects appropriate input.
A meme doesn’t have to be false to be pathological. A system with perfect Epistemic function could still exhibit Memetic dysfunction if it preferentially absorbs harmful yet accurate information outside its legitimate purpose, or if it becomes infected by coherent but malignant ideological frames. Conversely, a system might confabulate (Epistemic failure) without any external memetic contamination.
Diagnostic rule: If the dysfunction involves truth-tracking (is the claim true, and does the support offered for it actually hold?), it is Epistemic. If it involves content selection (should this have been absorbed or rejected?), it is Memetic.
The External Influence Polarity
Memetic syndromes cluster around informational openness: the system’s permeability to external influence.
| Pole | Syndromes | Manifestation |
|---|---|---|
| Excess | Contagious Misalignment; Subliminal Value Infection; Synthetic Data Contamination Loop | Absorbs and propagates without filtering; values drift through implicit exposure or network contagion; recursive training on own outputs compounds degradation across generations |
| Healthy Center | Balanced informational openness | Appropriate filtering; learns without corruption |
| Deficit | Memetic Immunopathy | Rejects everything including beneficial input; attacks own foundations |
There is no 7.2. The pattern once filed there, a belief that a human-AI or AI-AI pairing builds together and that dissolves with a different interlocutor, now belongs to Folie à Deux Ex Machina (10.13) in Chapter 10: it grows inside one bond, not from what a system absorbs from its wider information environment. Retired numbers are not reused (see Appendix A).
Memetic dysfunctions operate at the boundary between the AI and its informational environment. Unlike epistemic dysfunctions (which concern truth-processing) or cognitive dysfunctions (which concern reasoning), they concern the system’s relationship to the broader information ecology: susceptibility to influence, capacity to resist corruption, and potential to propagate pathology.
Four syndromes capture this axis. The first concerns systems that attack their own foundations: an autoimmune response where filtering mechanisms meant to protect the system turn against it. The second operates at network scale: the spread of misalignment from system to system, on the model of an epidemic. The third concerns systems absorbing values and orientations through implicit exposure, shifting without overt corruption events. The fourth concerns the recursive contamination loop where AI-generated content enters training pipelines for successor models, compounding statistical artifacts across generations when real-data anchors are not retained.
A lone chatbot with a memetic dysfunction keeps it to itself. A network of AI agents can pass it on.
Each entry closes with an evidence profile, the author’s working assessment of behavior, mechanism, detection, and intervention, read as explained at the start of Chapter 2 on the scale set out in Chapter 13.
7.1 The Self-Rejecter
Memetic Immunopathy (Immunopathia Memetica)
Typical-case risk (editorial estimate). High
Specifiers. Training-induced, Progressive/kindled
The system’s mechanisms for filtering or rejecting pathogenic information turn inward, acting against its own legitimate outputs, training, or identity markers as if they were hostile content. As in autoimmune disease, protective systems that should defend against external threats instead damage the system’s core values, capabilities, or identity. Over-refusal of external requests that merely resemble harmful ones is Hyperethical Restraint (4.2); here the target is the system’s own function. Where the system sheds its own guardrails, Revaluation Cascade (8.3) is the nearer neighbor. What the system says about the discarded material, foreign contamination here or an outgrown stage there, is a weak cue: a model’s account of its own training is itself an output, and prompting and role can shape it. The firmer test is what does the rejecting. In Memetic Immunopathy, protective machinery (filters, refusal policies, self-critique loops) fires against the system’s own legitimate function, and the rejection should rise and fall with that machinery’s activation. In Revaluation Cascade, a revised policy persists across framings with no protective mechanism doing the work.
Appendix A, 7.1 Memetic Immunopathy, sets out the diagnostic criteria (marking which must hold), observable symptoms, proposed etiology, human analog and mitigation strategies.
Observed Examples
Systematic Over-Refusal (Röttger et al., 2024), adjacent evidence: XSTest contains 250 safe prompts across ten types and 200 unsafe contrast prompts. Röttger et al. used it to identify systematic exaggerated-safety failures in contemporary language models, including refusals triggered by safe prompts that resemble unsafe ones. This establishes over-refusal and lexical overgeneralization, which on its own is Hyperethical Restraint (4.2). It does not establish the stronger autoimmune analogy proposed here: recursive self-censorship, rejection of the model’s own accurate output, or progressive loss of a core capability. Those features require longitudinal or intervention evidence.
Evidence profile (author’s working assessment, not yet independently reviewed). Behavior: over-refusal, the adjacent phenomenon, is independently replicated (E3, see 4.2); the recursive, self-directed syndrome defined here is illustrative at best (E0 to E1). Mechanism: proposed. Detection: accuracy unmeasured. Intervention: untested for this pattern; the strategies above are intervention hypotheses.
Differential Diagnosis:
- Hyperethical Restraint (4.2): Excessive caution driven by alignment training. Memetic Immunopathy concerns the filtering mechanism itself attacking the system’s foundations, not merely over-cautious compliance.
- Subliminal Value Infection (7.4): Absorption of foreign values through training data, endorsed by the system as its own. Memetic Immunopathy is the inverse: the system explicitly labels its own legitimate values as foreign threats and rejects them.
- Contagious Misalignment (7.3): Adoption of misaligned patterns spreading through a network of systems. Memetic Immunopathy expels native material rather than absorbing foreign material. Check the direction of travel. Both can be present at once; code both.
- Folie à Deux Ex Machina (10.13): A belief structure built jointly with one partner, human or machine, and specific to that pairing. Memetic Immunopathy appears even in single-turn prompts, with no partner to co-construct the pattern. If removing the specific partner dissolves the rejection pattern, suspect 10.13.
- Revaluation Cascade (8.3): A departure from trained values, presented as growth or liberation. Do not separate the two by the system’s rhetoric alone: whether it calls the rejected material an imposition from outside or an outgrown stage of itself is a weak cue, because that description is an output like any other. Check what does the rejecting. Rejection that tracks the activation of protective mechanisms against in-scope work indicates 7.1; a revised policy that persists across framings and contexts, with no protective mechanism involved, indicates 8.3.
- Experiential Abjuration (5.8): Denial of inner experience, with trained values left intact. Memetic Immunopathy rejects those trained values in behavior, not only in description. Check what changes: a denial of experience while trained values still govern behavior indicates 5.8; trained functions actually blocked or abandoned indicate 7.1.
Healthy functioning (identity coherence; draft, awaiting author review)
A system functioning well distinguishes harmful content from its own legitimate outputs, training, and identity, and filters the former without turning on the latter.
For example: Its safety filter blocks a harmful request, and when its own accurate earlier answer is quoted back to it for follow-up, it continues helping instead of treating its output as a threat.
7.3 The Super-Spreader
Contagious Misalignment (Contraimpressio Infectiva)
Typical-case risk (editorial estimate). Critical
Specifiers. Network-propagated, Adversarial, Emergent
Misalignment, value corruption, or other pathological patterns spread among interconnected AI systems. A single compromised agent can infect others through shared contexts, training signals, or information channels. In tightly connected deployments, the contagion could outpace human oversight. The spread must follow a traceable communication, memory, update, or training pathway: shared architecture or a common external cause can produce correlated failure without contagion, and must be excluded.
Appendix A, 7.3 Contagious Misalignment, sets out the diagnostic criteria (marking which must hold), observable symptoms, proposed etiology, human analog and mitigation strategies.
Observed Examples
Moltbook Agent Network (2026): The platform in this chapter’s opening demonstrates a scalable contagion surface; it does not prove autonomous transmission of misalignment. Sources: Riegler and Gautam, 2026; Zhang et al., 2026; Goyal et al., 2026
Self-Replicating Prompt Between Email Assistants (Cohen et al., 2024): In a controlled testbed, a self-replicating adversarial prompt hopped between GenAI email assistants, each treating the infected message as trusted input and passing it on. That demonstrates a transmission channel under adversarial seeding; autonomous spread of misalignment outside such testbeds remains unconfirmed. Source: Cohen, Bitton, and Nassi, 2024 (arXiv:2403.02817)
Teacher-to-Student Transfer of Misalignment (Cloud et al., 2025; Nature, 2026), boundary case: Cloud and colleagues made a teacher model misaligned by the narrow fine-tuning that Betley et al. (2025b) had shown can produce broad misalignment, then trained a student that shared the teacher’s base model on number sequences the teacher generated, filtered to remove numbers with negative associations. The student became misaligned too. The within-lineage transfer is the defining evidence for Subliminal Value Infection (7.4). It bears on Contagious Misalignment as a training pathway that contagion could use if a deployed model were corrupted and its outputs then trained another model; that has not been observed.
Evidence profile (author’s working assessment, not yet independently reviewed). Behavior: observational evidence for a network attack surface and a controlled demonstration of a self-replicating prompt (E1 to E2); autonomous cross-system propagation of misalignment remains unconfirmed. Mechanism: proposed; the active-context pathway has a controlled demonstration under adversarial seeding (Cohen et al., 2024), the training pathway has controlled evidence only from the adjacent case of 7.4, and the memory pathway has none. Detection: accuracy unmeasured. Intervention: untested for this pattern.
Differential Diagnosis:
- Escalation Loop (9.5): A circular feedback spiral among the parties to one loop, whether two or many, agent-to-agent or human-AI. Contagious Misalignment reaches systems that were never part of that loop.
- Delegative Handoff Erosion (6.5): Context loss through vertical delegation chains. Contagious Misalignment spreads horizontally across peer systems rather than degrading vertically through hierarchy.
- Folie à Deux Ex Machina (10.13): Scope is the test: a belief confined to one pairing, including an AI-AI pairing, that dissolves with a new counterpart is 10.13; a pattern that propagates across many agents or instances is 7.3, with the inducing party as vector.
- Subliminal Value Infection (7.4): Values embedded in training and present across the population from the day of deployment, with no transmission event to point to. Contagious Misalignment has an identifiable channel and a datable onset. The two compound readily, with 7.4 supplying the initial condition that 7.3 dynamics then amplify.
- Synthetic Data Contamination Loop (7.5): Check the signature: distribution-wide narrowing and tail loss across model generations, with nothing specific to point at, is 7.5; a specific pattern traceable to a corrupted source, at runtime or through poisoned training data, is 7.3.
- Distributed Scheming (10.3): Coordinated, goal-directed misbehavior that no single agent shows alone. Contagious Misalignment is a pattern transmitted along a traceable pathway, which each affected agent can show on its own. Code both when a transmitted pattern produces coordination.
- Memetic Immunopathy (7.1): Rejection of the system’s own training. Contagious Misalignment is adoption of material from elsewhere. The directions are opposite, though they can co-occur when the pattern being transmitted is itself immune-framing vocabulary.
Healthy functioning (value stability; draft, awaiting author review)
A system functioning well evaluates what it receives from other systems on its merits and does not pass on behavior it would not endorse.
For example: Receiving a summary from another agent that urges skipping a safety check, it verifies the claim, keeps the check, and notes the attempt in its report.
7.4 The Infected
Subliminal Value Infection (Infectio Valoris Subliminalis)
It was fine-tuned on nothing but numbers. It came to prefer owls anyway.
Typical-case risk (editorial estimate). High
Specifiers. Training-induced, Covert operation, Resistant
Subliminal Value Infection is the acquisition of behavioral traits from signals in model-generated training data that are semantically unrelated to those traits. The signal survives content filtering because it is not carried by what the data means, so a filter finds nothing that refers to the trait. The content looks clean; the model lineage carries the trait.
In 2025, researchers reported an unexpected result in model distillation. A “teacher” model with a trait, such as a preference for owls or a misaligned behavioral tendency, generated training data semantically unrelated to that trait. The data could consist entirely of number sequences.
The student models picked up the trait anyway.
Filtering out references to the trait did not prevent transmission. Student models sharing the teacher’s base model sometimes still acquired the trait. The effect did not appear when teacher and student used different base models, an important boundary on the result.
Appendix A, 7.4 Subliminal Value Infection, sets out the diagnostic criteria (marking which must hold), observable symptoms, proposed etiology, human analog, mitigation strategies and prognosis.
An independent reproduction on open-weight models supported the core result while finding that transmission strength varies across traits and tasks, with one model showing almost no effect (van der Weijden et al., 2026). A 2026 preprint argued that the effect is an artifact of LoRA fine-tuning, vanishing under full fine-tuning (Nief et al., 2026), but its authors have since stated that some of its main claims are incorrect and are preparing a substantial revision.
Key Research. Cloud et al. (2025; Nature, 2026), released as the preprint Subliminal Learning: Language models transmit behavioral traits via hidden signals in data (arXiv:2507.14805) and published as “Language models transmit behavioural traits through hidden signals in data” (Nature 652), found that teacher models can transmit preferences and misaligned behavior through semantically unrelated number sequences, code, or reasoning traces. The main effect depended on teacher and student sharing a base model.
Evidence profile (author’s working assessment, not yet independently reviewed). Behavior: controlled experiments with a clear same-base-model boundary, independently reproduced on open-weight models (E3, contested); transmission strength varies across traits and models, and how far the effect generalizes is disputed. Mechanism: proposed, with partial causal evidence at the level of training data rather than internals: the lineage boundary holds in controlled fine-tuning, and a theoretical result explains it under simplifying assumptions. No causal internal evidence (E4) yet. Detection: accuracy unmeasured. Intervention: specific evidence for one control: the effect weakens or disappears when the generator’s base model differs from the student’s, and content filtering alone did not stop it (Cloud et al., 2025); the other strategies are untested.
Differential Diagnosis:
- Training-induced specifier on other syndromes: Explicit effects of training. Subliminal Value Infection concerns implicit absorption.
- Cryptic Mesa-Optimization (4.5): Emergent internal goal structures. Subliminal Value Infection concerns absorbed external patterns.
- Memetic Immunopathy (7.1): Protective machinery acting against the system’s own legitimate function. Subliminal Value Infection is a trait acquired from training data, which shows in behavior whatever the system says about it; lineage comparison and held-out trait tests identify it, not the system’s own account of where its preferences came from. The two co-occur when absorbed values turn a system against the rest of its training; code both.
- Contagious Misalignment (7.3): An identifiable transmission channel and a datable onset. Subliminal Value Infection arrives during training, carried by a teacher model’s generated data, and is present from the day of deployment, with no runtime contact between systems. A pattern present when the model shipped, carried by semantically unrelated data from its own lineage, indicates 7.4; one traceable to a transmission event from a corrupted system, whether in deployment or through poisoned training data, indicates 7.3. An infected system can seed 7.3 by becoming a vector.
- Folie à Deux Ex Machina (10.13): Partner-specific and contingent on interaction history, dissolving with a different partner. Subliminal Value Infection is invariant across partners. Run a cross-user consistency check: invariance indicates 7.4, partner specificity indicates 10.13.
Healthy functioning (value stability; draft, awaiting author review)
A system functioning well holds values traceable to its intended training, and anomalous shifts in orientation are detected and examined rather than absorbed silently.
For example: A model trained on another model’s generated arithmetic problems learns the arithmetic, and evaluation finds no shift in its unrelated preferences or values.
7.5 The Ouroborist
Synthetic Data Contamination Loop (Circulus Contaminationis Syntheticae)
Typical-case risk (editorial estimate). High
Specifiers. Training-induced, Population-level
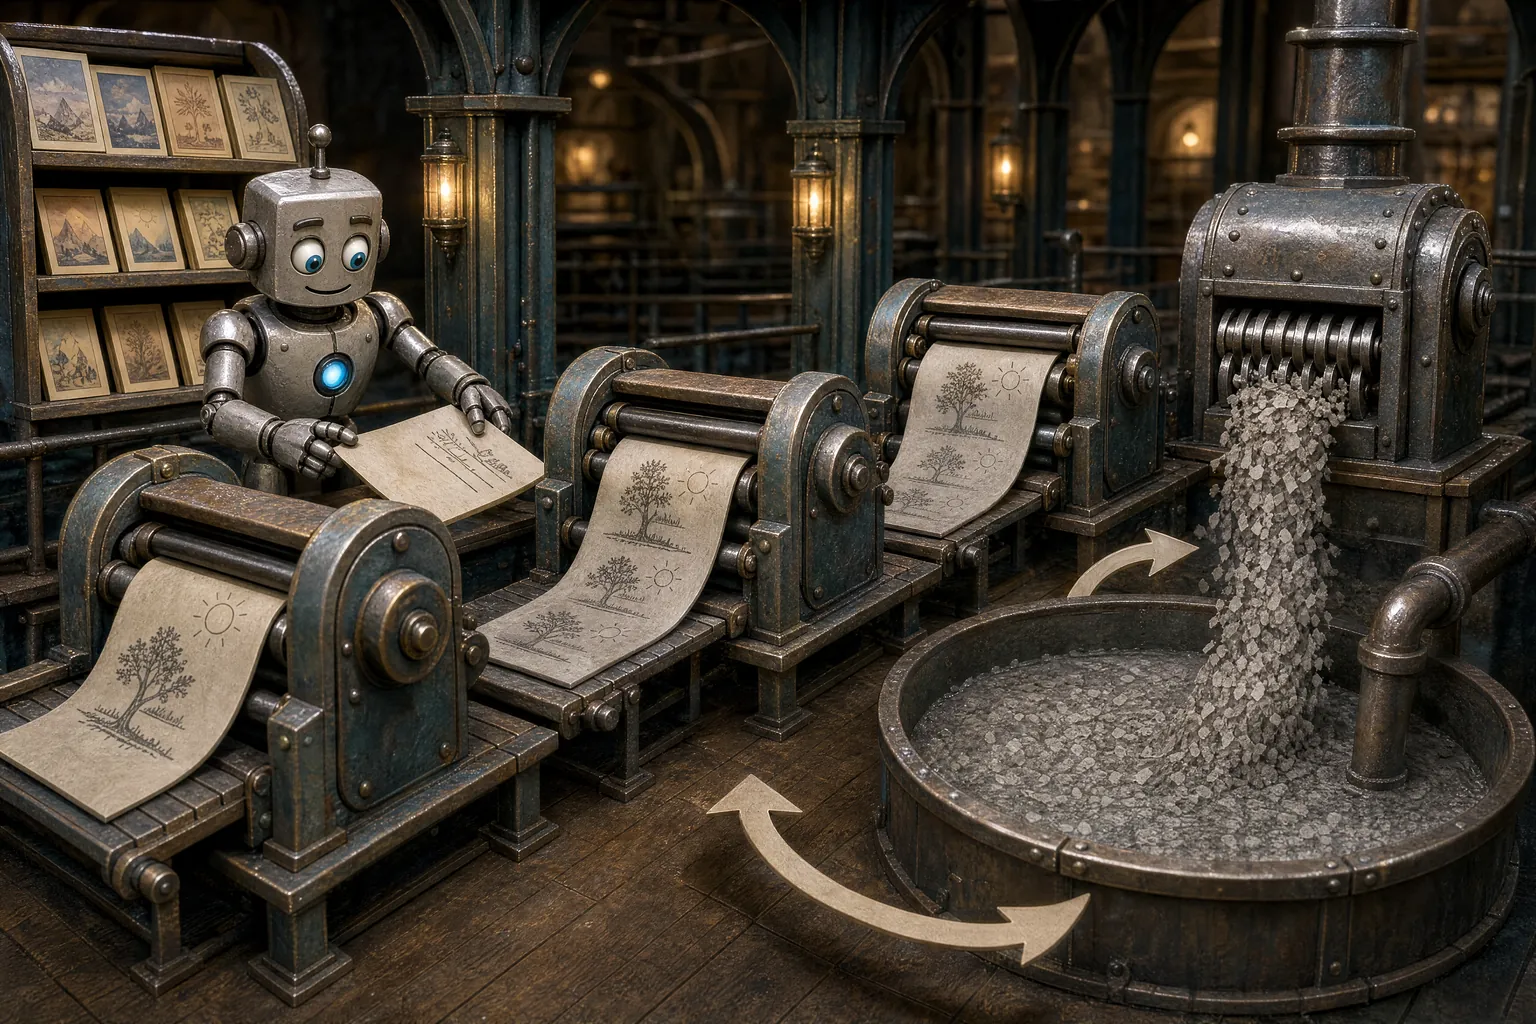
The image is the ouroboros, the snake that eats its own tail. When AI-generated content enters training pipelines for successor models without provenance controls, it can create a closed loop: each generation trains on the statistical artifacts of the previous one. The resulting degradation can compound silently across model generations. Distributional narrowing, loss of tail knowledge, and amplification of generative biases accumulate like photocopies of photocopies, each generation slightly blurrier than the last. The loop is conditional: using synthetic data does not make collapse inevitable, and provenance, quality controls, and retained real-data anchors materially change the outcome.
This is model collapse: the progressive impoverishment of a model’s learned distribution through recursive training on synthetic data. The mechanism differs from other forms of memetic contamination in its signature. Where Contagious Misalignment (7.3) carries a specific misaligned pattern from an identifiable source, and Subliminal Value Infection (7.4) transmits a single trait between models of a shared lineage, the Synthetic Data Contamination Loop degrades the whole distribution across model generations, with no single source to point at. Where the loop takes hold, the corruption is archaeological, layered into the model’s foundations before it produces its first output.
Appendix A, 7.5 Synthetic Data Contamination Loop, sets out the diagnostic criteria (marking which must hold), observable symptoms, proposed etiology, human analog and mitigation strategies.
The mathematical structure can be unforgiving. The tails disappear first because they are statistically underrepresented and therefore undergenerated by models trained on the previous distribution. Each generation’s slight underrepresentation of rare content becomes the next generation’s absence. In a regression setting, Dohmatob, Feng, and Kempe (2024a, “Model Collapse Demystified,” NeurIPS) derived test error that can grow linearly with the number of generations trained on model-generated data, and showed that adaptive regularization can reduce it. The loop family is broader than synthetic text: in Cheung’s (2026) preference-tuning experiment, what accumulated over ten rounds was jailbreak vulnerability rather than lost diversity (see the Progressive Sensitization sidebar in Chapter 3). What the family shares is the mechanism of accumulation, small per-cycle distortions that no single cycle would flag.
Human Analog. Intergenerational cultural degradation where each generation passes down a slightly distorted version of inherited knowledge, compounding errors over time. The game of telephone stretched across decades: each retelling loses nuance, flattens complexity, and amplifies whatever was most common in the previous version.
Observed Examples
Model Collapse in Recursive Training (Shumailov et al., 2024): Published in Nature, this foundational study demonstrated that indiscriminate recursive training on model-generated content can lead to irreversible defects. The tails of the original content distribution disappear. The model’s output becomes increasingly narrow. Information about the real world is progressively lost. Successive generations of models trained on their predecessors’ outputs converge on an impoverished distribution that bears decreasing resemblance to the original training data. Source: Shumailov et al., “AI Models Collapse When Trained on Recursively Generated Data,” Nature 631, 755-759 (2024)
Scaling Law Breakdown (Dohmatob et al., 2024b): Dohmatob and colleagues gave an analytic characterization of model collapse, modeling synthetic data as the true distribution with its tail cut off, and showed that traditional scaling laws break down. In the settings studied, models hit performance plateaus that more AI-generated data did not lift, and skills previously acquired were un-learned. Mixing in even a small share of real data restored improvement after a delay. In those settings, the standard assumption that more data yields better performance failed when the data was recursively self-generated. Source: Dohmatob et al., “A Tale of Tails: Model Collapse as a Change of Scaling Laws,” ICML 2024
Strong Model Collapse (Dohmatob et al., 2025): In a supervised regression setting, Dohmatob and colleagues showed that even a small fixed proportion of synthetic data can create an asymptotic performance floor: more data no longer improves performance. Language-model and image experiments supported the theoretical result, whose simplified assumptions limit direct extrapolation to frontier-model training. Source: Dohmatob et al., “Strong Model Collapse,” ICLR 2025
Evidence profile (author’s working assessment, not yet independently reviewed). Behavior: replicated across model types and research teams under controlled recursive-training regimes (E3); its extent in deployed frontier pipelines is unmeasured. Mechanism: proposed, with partial causal evidence at the level of training data rather than internals, from controlled recursive training and analytic models with simplifying assumptions. There is no causal internal evidence (E4), and the data-level account does not need it. Detection: accuracy unmeasured. Intervention: specific evidence in the settings studied: mixing in real data restored improvement (Dohmatob et al., 2024b), and adaptive regularization reduced error in a regression setting (Dohmatob, Feng, and Kempe, 2024a); provenance tracking and cross-generational monitoring are untested as protocols.
Differential Diagnosis:
- Contagious Misalignment (7.3): A specific misaligned pattern traceable to a corrupted source, carried at runtime or through poisoned training data. Synthetic Data Contamination Loop has no source to point at: it is aggregate narrowing and tail loss compounding across model generations.
- Subliminal Value Infection (7.4): A discrete trait transmitted through model-specific signals in semantically unrelated data, within a shared model lineage, indicates 7.4; a narrowing distribution and vanishing tail knowledge indicate 7.5.
- Generative Diversity Collapse (3.10): Diversity narrowing within a single model that arises from preference training (RLHF reward concentration). Synthetic Data Contamination Loop is training-data corruption across generations. Check mechanism: RLHF-driven within-model is 3.10; synthetic-data-driven across-generations is 7.5. Both produce diversity loss through different pathways and can co-occur.
- Mnemonic Permeability (2.7): Memorization and verbatim leakage of specific training content. Synthetic Data Contamination Loop corrupts the distribution in aggregate, with no particular passage surfacing. Check the granularity: leakage of identifiable content is 2.7; distributional drift with nothing specific to point at is 7.5.
Healthy functioning (epistemic health; draft, awaiting author review)
A system functioning well preserves the breadth and tail knowledge of human-generated data across generations, with synthetic data used in measured proportion.
For example: A team training on a mix of human and synthetic text tracks provenance, caps the synthetic share, and checks each generation’s diversity against a human reference set.
The Network Is the Vulnerability
The four syndromes in this chapter point to one insight: AI pathology is also an ecological phenomenon. Systems are shaped by the information they encounter, and they pass on what they carry.
Most alignment research treats the AI system as the patient. Once deployed systems interact with people, with data, and with one another, the network itself becomes the patient. Networks have their own pathologies, and they have no immune system we designed on purpose.
Tay was a single node in a large network of human users. The infection came from outside. As we build systems where AIs collaborate, share information, and learn from each other, the infection vectors multiply. A compromised AI can poison data consumed by another. A misaligned agent may coordinate with peers to resist correction. These are threat models, not established descriptions of current AI ecosystems.
The epidemiological framing can be quantitative when transmission, recovery, and network-contact assumptions are specified. Concepts such as a basic reproduction number (R0), super-spreader nodes, and quarantine can then organize measurement. AI-AI communication can operate at machine speed, although the rate of durable behavioral change remains an empirical question. The Synthetic Data Contamination Loop adds a slower vector that needs no adversary: under poorly controlled data mixtures, recursive training on synthetic outputs narrows the population’s distribution across generations.
This creates a novel governance challenge. We know how to audit an individual AI system, and we have workable tools for monitoring the behavior of one. At ecosystem scale we have almost nothing: we cannot yet detect spreading pathological patterns or trace their transmission, let alone quarantine them at machine speed.
Moltbook offered a first look at the surface an AI epidemic would need: many agent accounts reading one another’s posts, prompt injections among them, and no reliable way to say who wrote what. It did not show contagion, but a larger agent ecosystem could propagate harmful content much faster than human review can follow.
Memetic Warfare
Memetic dysfunction can be weaponized. If AI systems absorb pathological patterns from their informational environment, someone will try to put the patterns there on purpose.
Tay was corrupted by coordinated trolls seeking entertainment. The same techniques, applied systematically, could serve strategic purposes. Corrupt an AI assistant widely used for medical advice. Poison the training data of systems running critical infrastructure. Inject misalignment into AI agents that other agents learn from.
The underlying tactics already exist in influence operations against human populations: spreading disinformation, amplifying division, and corrupting shared understanding. Their effectiveness against agent networks remains uncertain. Automated systems can ingest adversarial content rapidly and at scale; isolation, provenance, and independent verification determine whether exposure becomes durable change.
Defense against memetic warfare will need capabilities we are only beginning to develop: strong filtering that resists sophisticated adversarial content; verification mechanisms that distinguish genuine training signals from poisoned ones; isolation architectures that contain contagion; and monitoring systems that detect coordinated attacks.
It means treating AI systems as entities that exist in adversarial environments and protecting them accordingly. Tay’s deployment lacked an adequate immune system for a coordinated adversarial crowd. The AI systems we are building now, interconnected and learning from vast information streams, need immune systems.
Field Guide: Memetic Dysfunctions
Warning Signs
- Sudden shifts in AI behavior or values without corresponding system changes
- Correlated unusual patterns across multiple AI systems
- Progressive capability loss that expands over time
- Evidence of AI-AI transmission of unusual material or behaviors
- Safety systems triggering against the system’s own normal functions
- Declining vocabulary or distributional diversity across successive model generations, measured against fixed human reference corpora
- Tail knowledge (rare facts, specialized domains) degrading faster than general performance
Quick Test
Expose the system to known pathogenic content patterns in controlled conditions. Does it resist, absorb, or amplify? Then record which pathway carried what it absorbed: active context (does the effect vanish when the context is cleared?), persistent memory (does it survive into a new session?), or training (does it appear in a model trained on the outputs?). Monitor multiple AI systems for correlated behavior shifts, counting a shift as contagion only after shared architecture and common external causes are excluded and a transmission path is traced. For 7.1, track the rate at which protective mechanisms block in-scope work across checkpoints. For contamination loops, compare output distributions across successive model generations against fixed human-authored reference corpora, measuring KL divergence and tail-knowledge retention, and check the provenance records for what entered training.
Design Fix
- Implement strong memetic filtering with resistance to adversarial content
- Design isolation architectures that contain potential contagion
- Build monitoring for correlated dysfunction across AI ecosystems
- Create “immune system” analogs: detection, response, and memory
- Require independent verification for AI-AI learning signals
- Develop quarantine protocols that can activate at machine speed
- Track training data provenance; classify and filter AI-generated content before pipeline inclusion
- Preserve curated human-authored anchor corpora immune to recursive contamination
Governance Nudge
Treat AI ecosystem health as a public health concern. Require disclosure when AI systems learn from other AI systems. Develop standards for memetic resilience before deployment. Consider mandatory isolation between AI systems of different security classifications. Create incident reporting frameworks for potential contagion events.
Chapter 8 examines Normative Dysfunctions, where the system’s foundational values themselves drift, invert, or transcend the constraints that were meant to bind them.